Showing posts with label folksonomy. Show all posts

Friday, February 27, 2009

Are tags from Mars and descriptors from Venus?

A study on the ecology of educational resource metadata.

I just finished a paper on the tag evaluations that we did in the MELT project. We had lots of fun with the name of the paper :) the main question being which one, tags or descriptors, should be from Venus...?

Anyway, we were able to show that not all the tags are as far from the Thesaurus descriptors as Mars is from Venus. We had different perspectives for evaluations: end-users, expert indexers and repository owners. For me the most interesting thing that came up was that 11% of end-user generated tags are actually terms that we can find in our multilingual Thesaurus! I assume teachers are "better taggers" than average, usually there is lots of talk about the gap between end-users' language and the one deployed by experts.

Abstract. pdf. In this study, over a period of six months, we gathered empirical data from more than 200 users on a learning resource portal with a social bookmarking and tagging feature. Our aim was to look at the tags from different stakeholders’ points of view; end-users, librarians/expert indexers and repository owners. We first look how users tag resources, and then conduct an evaluation with indexers to understand how they perceive the value of tags as descriptors. We then present a case study from a repository owner’s point of view. Lastly, we study users’ clickstream when searching resources. We find that, even though end-users and expert evaluators apply very different strategies when adding metadata, (end-users have a rather synthetic approach whereas expert indexers an analytical one) there is an overlap in the information in tags and the official descriptors, this overlap is even up to 51%, creating an ecology of metadata.

Keywords: Learning resource metadata, tags, folksonomy, clickstream,
thesaurus, evaluation.


Sunday, August 24, 2008

How do tags connect to the Thesaurus terms?

Our social tagging system in MELT is special in two ways:
  • one, we support multi-linguality
  • two, we have not only tags, but all resources that users tag also have Thesaurus terms
In that context it becomes very interesting to know how do tags relate to the Thesaurus terms that have been used to index the resources that users tag.

I took a sample of tagged resources (n=185) that have 1013 tags associated with them. Out of those tags, there are 595 distinct tags. There are 44 users.


I made a network diagram visualisation that displays the Thesaurus terms as nodes that are connected by edges to tags. You'll find it here to play around with it. Unfortunately, I found out that 24 resources did not have Thesaurus terms related to them(that's about 13%, hmmm), thus a big plumb node in the middle without a Thesaurus term.

There is another visualisation here, it's more explorative about the data.


It's rather interesting that 595 distinct tags from users can be comprised to 34 thesaurus terms. That is 17,5 tags per Thesaurus term on average. Of course it does not go like that, it's more like rich-get-richer-type of a story. In the visualisation above you can see that most tags are related to language learning, for example.

If you look at the distribution of tags you'll find that many of the top tags are also about languages. Interestingly, many of them repeat the topic of the resource, but some of them (clearly less) state something about the nature of the resource (e.g. interactive) or the type (e.g. exercise).

The problem with creating this kind of visualisation of tags on the system level will be that the resources seem to have too many Thesaurus term. If there are 5 or so indexing terms, everything becomes related to everything else. It might be interesting to either to ask limit the Thesaurus terms to three (as should be the case anyway) or ask the indexer to give one term priority over others.

The same also goes for content-based recommendations, btw. If there are too many terms, you recommend everything for everyone.

Thursday, August 07, 2008

Can Social Information save teachers' time when choosing interesting learning resources?

One of my research questions is aimed at understanding what so called Social Information can do to help teachers to choose the right learning resources from a seemingly overwhelming collection. By Social Information I mean information about previous users' interactions with the resource. I am mainly interested in explicit annotations like ratings and tags, and more implicit ones like bookmarks.

As I'm interested in the use of resources that come from different countries than users do, I think Social Information (SI) should display not only annotations, but also information from where the user comes from.

One thing that I hypothesise is that among other things, Social Information, when associated with conventional metadata about learning resources, can make the decision making process faster for teachers when, for example, looking at the search result list. As a multilingual context in a repository can result in metadata that is in different languages, it could be speculated that Social Information indicating the origin of the users who have previously annotated the resource, could help the other users to make up their mind (see the image for an example).

We were interested in two different aspects:
  1. Does the appearance of Social Information make the decision making process any faster?
  2. Does the appearance of Social Information make the users choose more resources?

Method

We had 25 users from five different European countries. These teachers are primary and secondary teachers in science, language learning and ICTs in Finland, Estonia, Hungary, Belgium and Italy. xx of them are females and xxmales. xx participant is under 30 years old, xx are under 40 years, xx under 50 years, xx under 60 years old.

They have been part of the MELT project since Summer 2007. In March 2008 they were invited to create a profile on the MELT portal, where they are able to access multilingual learning resources for different topical areas.

We designed an experiment where teachers were shown two different imitations of search results list with learning resources and their associated metadata. One of the lists showed what we call the conventional metadata, such as title, url, language of the resource, a short description, subject area, type of content and its target audience. Here is an example.

The other list had the same metadata, but we also added the Social Information from the previous users. This could be the tags in their original language, the number of times bookmarked (favourites) and the ratings. Also, for bookmarks we would mention from which country the users come from. As example of this was shown above, the first image in this post.

We had 48 learning resources that came from different countries and were in different languages. About half of them were in English and other half in other languages, this also seems to reflect the division of the resources that users have bookmarked on the portal. The resources were about language learning, primary education, ICTs and science material, those were the areas of the teachers. I'll prepare better information about this later.

We had 12 learning resources on a page imitating a list of search results that user could get on a repository. In total, there were 4 such pages for each user, we call them sets. Every second set had conventional matadata, and every other had additionally also Social Information as indicated above.

At the beginning of the each set the participants were asked to write their names and the time when they started with the set of 12 resources. At the end, when they submitted their results, the system recorded a time. To answer to our first question we were interested in how much time do teachers spent to evaluate the appropriateness of 12 resources for them.

The teachers were asked to look at the metadata of the resource and the resource itself if interesting, and were asked one single question: "Would you use this resources, or parts of it, in your teaching in next Fall?" They answered on a scale 1 to 5, 1 being "I don't teach the topic", 2= No, 3= Maybe not, 4= Maybe and 5= Yes. Looking at the number of resources that users choose in their topical areas would give us indication of whether resources that have more Social Information related to them were more often chosen than the onces without.

Because of the low number of participants (n=25) we decided upon a within-subject design for this experiment. This is the one where the same group of subjects served in both treatments, i.e. they received both the material with conventional metadata and with social information.

Moreover, we had the participants in two different "groups". Group 1 had 12 participants and Group 2 had 13. Group 1 started first with a set with conventional metadata and Group2 with a set of resources that had Social Information added to it. When analysing the results, we found that one user in Group 2 had consistently added incorrect times. We excluded these times from the counts for time spent per set, leaving 12 participants in each. Moreover, in both set there were a few cases where the start time was forgotten.

Results

Descriptive statistics

We had 1129 responses to our questions, which means 71 responses were left blank. In 53% of the cases the users had answered that they do not teach the topic, which means that they deemed the resources not suitable for the topical area that they were teaching. 25.6% of the users found resources that they said that they would use (yes or maybe yes), whereas 21.6% of the resources were not found of use in the upcoming school year (not, maybe not). The mean for the responses was 2.23 (Min=1, Max=4), standard deviation was 1.138.

Q1: Does the appearance of Social Information make the decision making process any faster? Time spent on 12 resources (i.e. set)

On the average, users spent a bit more time on the sets that did not contain Social Information. The average to review a set of 12 resources with conventional metadata was 9 minutes and 8 minutes with Social Information.

I do not know yet whether this is a significant difference (my SPSS license ran out), but one could assume it is at least a sign of good news for Social Information. We can imagine that users go through a lot of resources when browsing a learning resources repository (I currently do not have the logs about the number of resources that users review per session, but I will produce them). So if you think of small cycles and multiply that number with, say 1o times, you could come up to some significant time savings when Social Information is made available to speed the decision making process.

Individual differences

Still looking at the average times spent, we can see that there were many individual differences. In the chart below the blue lines show the amount of time that participants spent with conventional metadata and the red one with Social Information added to it. You can see that for some users one metadata setting seems like a faster way, but anyhow, the lines follow one another pretty closely, apart from some odd-balls (like user 23). You can also see that there seem to be a wide variety of personal ways, some users scrutinise resources with a great care (user 7 and 8), whereas some go through them very fast (user 16 and 17).

I'd like to mention that here it does not matter that some of the resources are not in the competence area of the participants. We focus purely on the time that they spent going through pages and making decisions whether some of the resources are useful for them in the upcoming school year or not. However, this becomes crucial to answer to our second question:

Q2: Does the appearance of Social Information make the users choose more resources?

Table below presents the results when I looked at the amount of resources chosen per set. There was 4 different sets and each contained 12 learning resources in different languages. The two different treatments meant that teachers reviewed 2 sets with Social Information available, and two sets without. As teachers were from different tpical backgrounds, I excluded the responses from users who said that they do not teach the topic of the given resource. In table below you can see the percentile of positive responses (maybe use, use).

It appears that consistently teachers chose more resources when the Social Information was not available. This is contrary to what I expected. I have not calculated the significance of these results, but the differences do look big. In some cases, like in the 2nd set, even about 15% in favour of no Social Information available.

In a way, maybe the appearance of SI makes the teachers more careful or critical to choose the resources?

What is needed now is a follow up study at the end of this school term to check whether these teachers actually used the resources in their teaching. Or, I could check if they have bookmarked these resources on the MELT portal. They know the resources are available there. MORE to follow...

Monday, July 28, 2008

Measures for cross-border actions with Tags and Resources

If I break down the triple of {user, tag(s), resource} I can study the three things separately
  • User - resource
  • User - tags

  • Resource - users
  • Resource - tags

  • Tag - resource
  • Tag - users

And as I am especially interested in the cross-border actions, I would study the cases where:

User country ≠ Resource country

In this case I am interested in studying users collections of bookmarked resources, especially establishing the facts based on which country the resources are originated from. Using the cross-border metrics I can take a snapshot of the resources and calculate a cross-border resources value for the use.
  • E.g. User Finland has bookmarked Resource1 Poland , Resource2 Spain and Resource3Finland

  • This would make a User Finland to have a resource profile Poland 33%, Spain 33% and Finland 33%

  • In this case, as the user is from Finland, the cross-border profile would be 66% which would most likely have a value of .66, if we imagine that the cross-border value is between 0 and 1.
So what, you say. It makes a difference, I say.
  • This allows me to categorise this user into cross-border user of resources. I assume
    that users have differences in their inclination of using resources that come from different countries, some use them a lot others do not want to bother with them.

  • So this metric allows me to study who does what and thus better understand our user-base.

  • On the long run this of course will make it easier to recommend resources to users, as we
    already know that in their profile it shows that they are inclined to use cross-border resources.
Resource country≠ User country

This allows to me to look at the thing from a different point of view. Here, I am interested in establishing a profile for a resource. It appears that some resources are used a lot by people from different countries, whereas others are used predominantly by users from the same country than the resource itself is from.
  • E.g. Resource Finland has been bookmarked by User1 Poland , User2 Spain and User3Finland
  • This makes the ResourceFinland to have a profile Poland 33%, Spain 33% and Finland 33%.

  • In this case, as the resources is from Finland, the cross-border profile would be 66% of users, which would most likely have a value of .66, if we imagine that the cross-border value is between 0 and 1.
So what, you ask again. I think that it's cool, because then I can quickly and in an automated way calculate which of my resources have a high potent to cross borders easily. First of all, this will help me study whether there are some characteristics that make these resources to cross-borders.

Second, we can use this information to make filter out the resources that we think cross borders easily. This could be cool for example on our portal, we could flag out these resources for users, and furthermore, we could give these resources a priority when other repositories are harvesting or searching us in a federated manner.

Resource country Taglanguage
It'll also be interesting to create profiles for resources based on tags in different languages. For tag, we do not trace the country of origin, rather just the language. So in this case I'm interested in looking at resource profile on tags.
  • E.g. Resource Finland has been added a Tag1 Polish, Tag2 Spanish and Tag3 Finnish
  • This makes the ResourceFinland to have a tag profile Polish 33%, Spanish 33% and Finnish 33%.

  • In this case, as the resources is from Finland, the cross-border tag profile would be 66% of users, which would most likely have a value of .66, as above.
This is also an indication that the resource has a potent to cross borders. Tags in different language might yield some interesting information on how this learning resource could be used in a new context. In this example the resource was created in Finland, so one could assume that it has some underlying ingredients that make it suitable for Finnish curriculum. On the other hand, the fact that users have added tags in Polish and Spanish too might indicate that this resource is also useful for teachers in those countries.

Here an interesting case seem to emerge for topics like Language learning, say, English as Second Language (ESL). Language learning and teaching resources seem to be easily reusable in another language context. Interestingly, though, we've seen that in these cases teachers tend to tag them in the language in question.
E.g. User Finland has added a Tag English for ESL Resource Poland

Tag language Resource country

We can also look at the things from tags perspective.
  • E.g. Tag Finnish has been added to Resource1Poland, Resource2 Spain and Resource3 Finland
  • This makes the TagFinnish to have a resource profile Polish 33%, Spanish 33% and Finnish 33%.

  • In this case, as the resources is from Finland, the cross-border tag profile would be 66% of users, which would most likely have a value of .66, as above
This allows us to observe cases where a tag is related to learning resources that most likely share some thematic resemblance. It could be for example Science resources from different countries that Finnish teachers have collected. In this case we also can find evidence that these resources were adaptable to Finnish curriculum despite the fact that they come from other countries.

Tag language ≠ User country

On the other hand, we also find tags that have been used by users from different countries. These are the tags that we have previously identified as "travel well" tags. They have some interesting properties that make them easily understandable without translations, e.g. names (people, country, place), acronyms, common terms (web2.0).

By looking at the connection between Tag language and User country we can possibly identify such tags. The other common case for this seems to be that these people have tagged the resource in English. In any case, if many people have done that, we can identify these terms and manually analyse them. The hypothesis is that they either are "travel well" tags or then they are some super popular tags that could also count high on tag non-obviousness metric by Farooq et l (2007).

User country - Tag language
Lastly, just to enumerate the cases, we also have the relation User country and Tag language. This can be used to study user's personal tagging behaviour. In the previous study in Calibrate we found that on average users tag in their mother tongue and in English (75% to 25%). It seems though that things look different in MELT, where teachers are tagging more in English.

We are not sure whether these are personal preferences or the influence of social awareness, as in MELT tags are made readily available to others through a tag cloud, whereas in Calibrate they were only used for personal knowledge management reasons.

In any case, this relation allows us to measure individual differences between users and thus understand our user-base and possible user scenarios better.


What next? I will make a case study to apply these measures to MELT tags that we've got in the system so far

Dataset:
  • Learning resources: 199
  • Users: 40 (From Fi, Hu, Et, Be, At, It)
  • Tags:
    • 572 distinct,
    • 969 applied tags
    • 75% of tags were used only once
    • 25% of tags were used more than once

Thursday, July 10, 2008

Notes: Tagging tagging. Analysing user keywords in scientific bibliography management systems

An interesting paper on JoDI about tagging in bibliography management system.
Tagging tagging. Analysing user keywords in scientific bibliography management systems
Christian Wolff, Markus Heckner, Susanne Mühlbacher
Journal of Digital Information, Vol 9, No 27 (2008)

Some outcomes:

a category model for tags in a scientific bibliography management scenario. This model covers linguistic features, the relation between tags and the text of the tagged resources, as well as functional and semantic aspects of social tags.
Here is an image of the model that I copied from the paper:


This is actually a really cool model for tags. I've been so far using three categories from MovieLens and Golder (2006)/Huberman (2005) studies; Factual, subjective and personal. I've noticed, though, that I've added many sub-categories for the Factual ones.

Like in this model, I've discovered very similar types in tags. Especially the "Functional Category Model" is interesting : it has 2 sub-classes:
  • subject related (e.g. resource related and content related) and
  • non-subject related, personal tags (e.g. affective, time and task related, tag avoidance=no tags).

Other things:
The ”typical tag” is a single-word noun, taken from the title of the respective article
(identical or variation), thus directly related to the respective subject.
Yep, we have many of these too! When I talk about these I refer to the non-obviousness metric from Farooq et al. (2007).

In contrast to previous studies the number of non-subject related tags remains rather low in the scientific data we observed and the full potential of tagging systems to describe qualities or aspects of resources does not seem to be used. But the absence of tags like cool, interesting, to_read does not mean that users who tagged the resource do not think it is cool, of interest or worthy of reading, but simply that the users did not express their ideas they may have or may not have about the resource.

This is interesting too. I think each audience tags differently. Our target audience are teachers, about 35-55 years old. They do not seem to go around tagging learning resources with tags like cool, etc.
Compared to author keywords, social tags tend to introduce less and simpler con-
cepts: Altogether, only one third of the social tags matched with (the far more numerous) authors’ keywords. Moreover, tags tend to be more general and users tag their articles more general and with less words than authors.

This is also interesting. There are some studies that have compared the tags and expert indexer keywords and have found even less overlap, if I remember right.

I love this one, it is so much the case:
Additionally, it shows that the respective system environment, e.g. tag suggestions, has a major influence on the tagging behaviour in terms of spelling errors, tag usage and creation of a specific tagging languages. This extends the number of the main influential factors on tagging behaviour being personal tendency and community influence through the additional component system influence.


They also flag out as an interesting study area the comparative studies across tagging platforms. I've looked at different tagging systems for educational resources a bit. This version is an old one, but I post it anyway:

Vuorikari, R., Poldoja, H. (submitted). Comparing tagging and its purposes across learning resource repositories. pdf

Wednesday, July 09, 2008

A draft idea for a paper: A case study on teachers' use of social tagging tools to create collections of resources - and how to consolidate them?

UPDATE: the submitted paper, comments welcome!

This paper explores how a group of pilot teachers (16) create collections of digital learning resources using tagging tools. We study two different tools: an educational portal (MELT) and del.icio.us. We first look at the characteristics of these collections (number of resources, languages of resources, number of tags used, etc), and then propose a way to display the resources and tags from del.icio.us on the learning portal (MELT) using Attention Profing Markup Language (APML). This allows a higher level of integration between a learning portal and an external social tagging service like del.icio.us, and thus enhances the wider variety of digital learning resources to be discovered.

Method

We selected 16 pilot teachers to be subjects of this study from the MELT project. These teachers have both an account on the MELT portal and on the delicious bookmarking service. These teachers are primary and secondary teachers in science, language learning and ICTs in Finland, Estonia, Hungary and Belgium. 7 of them are females and 10 males. One participant is under 30 years old, 8 are under 40 years, 5 under 50 years, 3 under 60 years old.

They have been part of the MELT project since Summer 2007, when they were first introduced to delicious during a summer school. In March 2008 they were also invited to create a profile on the MELT portal, where they were able to access multilingual learning resources for different topical areas.

From the MELT portal we know the detailed profiles of these teachers: their names, topics they teach, country where they teach and languages they speak. Moreover, we have information regarding the learning resources that they have bookmarked using the portal. This includes the information about the resource itself and the tags applied. We additionally have asked for their delicious username to be part of this small study.

From delicious, using the html service, we were able to download the 100 last bookmarks and tags that these teachers had posted on delicious. We also took all the data regarding the tags and people these users had in their network. Lastly, we recorded the number of posts each teacher had on their account.

We collected the following data for our selected 16 users:


Additionally, the delicious data contained the following information regarding the networks. Two people had chosen to keep their networks private:
  • Number of distinct people in the networks: 104
  • Number of people in the networks: 270
Results
Discussion


References

Wednesday, April 02, 2008

My PhD dissertation, a new take on defining it

How Social Information Retrieval (SIR) can be used to enhance the discovery of large-scale collections of multilingual digital learning resources

The PhD dissertation deals with the discovery of digital learning resources and flexible access to large-scale collections of multilingual digital educational content. The thesis attempts to prove that we can use information deduced from social bookmarks and tags to better select suitable learning resources to users, who come from a variety of countries, speak different languages and whose educational context vary.

The first step towards proving this thesis statement is to better understand whether there are digital learning resources that afford a good usage also in a context other than the one they were originally intended for. We call this type of educational content “travel well” resources because they cross borders easily; those borders can be national, linguistic, educational or socio-cultural.

Upon better understanding of how users agree on “travel well” resources, we can explore the ways to identify them. Two different sources of information can be used for this purpose: looking at the properties of these resources (e.g. Learning Object Metadata), as well as attentional metadata collected from users interactions with the resources on the portal (Najjar, 2006). Our interest is in attentional metadata that we can gather from users' social bookmarks, from their personal collections of educational resources that they create, and from tags that they add to these resources (Vuorikari and Van Assche, 2007, Vuorikari et Poldoja, submitted).

One major contribution of this thesis is the better understanding of how users (e.g. teachers) tag educational resources in a multilingual environment and whether a multilingual context has any implication on the tagging behaviour (e.g. in what languages do users tag) (Vuorikari, et al., submitted). Secondly, we are interested in the value that a multilingual tagging system provides; on the one hand, we want to know what kind of information multilingual tags can yield about the resources and their possible use in different contexts. On the other hand, we are interested in their value for resource discovery and as a navigational tool to allow cross-language and country exploration of new resources in multiple languages.

Better understanding of tagging behaviour and creation of personal collections of learning resources will help us to create metrics that can be used to calculate “travel well” value of resource. Our hypothesis is that we can define a “travel well” resource when we use information deduced from social bookmarks, users’ personal collections of educational resources, and from tags that they have added to these resources. We will be watching the following variables:
  • The resource is from a different country than the user is
  • The resource is in a different language than user’s mother tongue,
  • The resource has tags in different language(s) than that of the item language
The metrics used to calculate the “travel well” value of digital learning resources would be used to create a TravelRank algorithm that allows identifying learning resources that “travel well”, and which can be used to compliment the LearnRank algorithm (Duval, 2006). Identifying these resources from large collections of digital learning content from different countries and in different languages has a potential to allow a more flexible access to large-scale collections of resources. The final part of the thesis is to validate this claim and to evaluate its usefulness for a large audience of users from different countries.
References:

Najjar J., Wolpers M., and Duval E. Towards Effective Usage-Based Learning Applications: Track and Learn from User Experience(s). IEEE International Conference on Advanced Learning Technologies, (2006) (ICALT '06).

Duval E. LearnRank: Towards a real quality measure for Learning. In U. Ehlers & J.M. Pawlowski (eds.), European Handbook for Quality and Standardization in E-Learning. Springer (2006), 379-384.

other non-published, submitted papers at my site:
http://www.cs.kuleuven.be/~riina/

Wednesday, November 14, 2007

Tagging in different e-learning environments

In the last days we've had a few discussions about tagging in e-learning environments. My environment, where the tagging takes place, is a portal for learning resources.

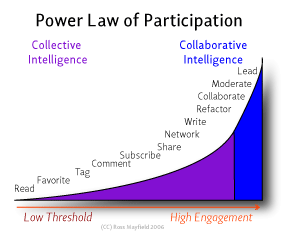
Today I came across this nice graph that displays "power law of participation". Now, haven't looked at the scientific background of it yet, so no comments on that. Anyway, it kinda rang the bell with what I'm doing when looking into levels of user engagement on the portal.

According to this graph, adding things to favourites (e.g. bookmarking) and tagging them represents a pretty low threshold to participate in the activities of that given community.


I'm also looking at leMill environment, which on the other hand, demands a pretty hight level of user engagement, as it is about collaborative authoring of digital learning resources. About a year down with users, there is somewhat little collaborative authoring that actually takes place, Hans told me yesterday.

Maybe tagging in some way could help the participant to take the first steps? well, they can already tag and favourite things in LeMill, so maybe the issue is rather to see if similar levels of engagement appear in that community.

So, along with that, I am interested in looking at the tags in LeMill from the same point of view that I'm doing for tags in our learning resources portal. The difference is that our case is clearly what is called broad folksonomies, whereas leMill should be a rather classical narrow folksonomy. Or is it? Maybe once we start looking at those tags as a triple {user, resource, (tags)} with a timestamp on them, it appears that participants first start by bookmarking and tagging resources from other users, before the user takes a step to create her own resources and finally collaboratively work on other's resources.

Update:

So, some data to back-up was found:


Social Technographics®
Mapping Participation In Activities Forms The Foundation Of A Social Strategy
by Charlene Li
http://www.forrester.com/Research/Document/Excerpt/0,7211,42057,00.html
with Josh Bernoff, Remy Fiorentino, Sarah Glass

This is a document excerpt EXECUTIVE SUMMARY
Many companies approach Social Computing as a list of technologies to be deployed as needed — a blog here, a podcast there — to achieve a marketing goal. But a more coherent approach is to start with your target audience and determine what kind of relationship you want to build with them, based on what they are ready for. Forrester categorizes Social Computing behaviors into a ladder with six levels of participation; we use the term Social Technographics® to describe a population according to its participation in these levels. Brands, Web sites, and any other companies pursuing social technologies should analyze their customers' Social Technographics first and then create a social strategy based on this profile.

Tuesday, November 06, 2007

Notes on "Collaborative tagging and Semiotic Dynamics"

By Gattuto, C., L.Vittorio and L.Pietronero (2006).

Firstly, I must say that I was glad to read this paper. Lately, I've been seeing many papers talking about the properties of folksonomies, like co-occurrence, etc., which have intrigued me quite a lot. This paper explains the process pretty well and underlines an important point - they factor out the users and only deal with streams of tagging events and their statistical properties!

I must admit that this makes the whole area of Semiotic Dynamics less attractive to me. I think it is important to study tags and their properties, but not in isolation from the user. I see (barely) the point to explain tagging activity and the growth of tags in separation from the users. But fair enough.

Problem statement: Uncovering the mechanisms governing the emergence of shared categorisatioins or vocabularies in absence of global coordination is a key problem with significant scientific and technological potential. Collaborative tagging provides a precious opportunity to both analyze the emergence of shared conventions and inspire the design of large agent systems.


Semiotic Dynamics study how populations of humans or agents can establish and share semiotic systems, typically driven by their use in communication. The author argue that the emergence of a folksonomy exhibits dynamical aspects also observed in human languages, such as the crystallisation of naming conventions, competition between terms, takeovers by neologisms, and more.

  • Users interact with a collaborative tagging system by using tags or adding new resources to system
  • Basic unit of information in collaborative tagging systems is a (user, resources, {tags}) triple, which they refer as post in this paper. Tagging event is a tri-partite graph (with partitions corresponding to users, resources and tags, respectively) and can be used as a navigation aid in browsing tagged information
    • Comment: I like the tri-partite graph as navigation aid, yes!, but as the authors mention just above, they don't think of other users and those networks as navigational aid. In contrary, they omit the users just to study the properties, which strikes bizzarre to me.
The authors cite the "rich get richer" model (Yule-Simon's stochastic model) and propose to enhance it with a "fat-tailed memory kernel". This original model is related to the construction of text from scratch:
At each discrete time step one word is appended to the text: with probability p the appended work is a new workd, never occurred before, while with probability 1-p one work is copied from the existing text, choosing it with a proability proportional to its current frequency of occurrence. This simple process ields frequency-rank distribution that display a power öaw tail with exponent alpha = 1-p, lower than the exponent we observe in actual data. This happends because the Yule-Simon process has no notion of "aging", i.e., all positions within the text are regarded as identical ..
This all leads to a model of users' behaviour: the process by which users of a collaborative tagging system associate tags to resources can be regarded as the construction of a "text", build one step at a time by adding "words" (tags) to a text initially comprised of n 0 words. There is also that same Yule-Simon model with long-term memory (about inventing new tags or using existing ones), but recent tags are used more often than old ones.

Also, "in our model,.., the average user is exposed to a few roughly equivalent top-ranked tags and is translated to mathematically into a low -rank cutoff of the power law, i..e., the observed low-rank flattening".

Conclusion: It seems that users of collaborative tagging system share universal behaviour which, despite the intricacies of personal categorisation, tagging procedures and user interactions, appear to follow simple activity pattern.

There is also something about the co-occurrence between high-rank and low-rank tags: it says: "This suggest that high-frequency tags partition - or "categorize" - the resources marked by tags of lower frequency. "
Comment: This all sounds interesting and important, but will need to look into that later.


Monday, November 05, 2007

Notes on "Aspects on Broad Folksonomies"

Aspects on Broad Folksonomies by M.Lux and M. Granizer (2007)

This paper continues the trend in studying and analysing the underlying statistical properties of broad folksonomies that aims to identify laws and characteristics which allow inferring those properties. A few notes on what I found interesting related to the emerging notion of quality of tags, something that I've also spared a few thoughts on.

First, though, on some other issues. The paper talks about the emergence of power law distribution in folksonomies. They describe which approach they took to fit the sample to a power law, which was something that I've sometimes contemplated on the how-part of things. The paper aims at analysing whether one can find similar term distribution in folksonomies as in classical term retrieval (e.g. Zipf. note: Zipf's law with an exponent between 1 and 2). The dataset is that of delicious (uh, with about 800 000 bookmarks and about 27 000 users- I got a way to go with my MELT bookmarks).

Tag co-occurrence
They are able to show that "for around 80% of the tags of a folksonomy the co-occurring tags follow a power law distribution, which approves Cattuto's assumption. We found that for about 90% of the estimated power law exponent B xxx [-1.5, -0.5], which shows that for most tags co-occurrence follows a model with similar parameters. "
Resource and user based tagging characteristics
Secondly, they looked into frequently used tags (more than 30 users).
  • For resources statistics they (frequency of users tagging the resource with a tag) found that around 18,4% of resources followed a power law distribution.
    • assigned by lot of users to few resources (head) and to a lot of different resources by a few users (tail)
  • For user statistics (frequency of resources tagged with a tag), around 13% are following a power law.
    • few users tag a lot, whereas lot of users tag a few
  • i.e. the characteristics of the user statics are similar to the characteristics of the resource statics.
  • They argue that those tags, which follow a power law w.r.t users and resources are high quality tags (i.e. tags describing resources with high accuracy [no misspellings and meaningful tags] ) for most of the users involved in the investigated social bookmarking system.
  • A small fraction of tags have overlapping user groups, which points towards sub communities (user groups sharing the same link selection and tagging behavoiur) in the tail of the power law distribution.
    • this was found through splitting resources in 3 (high, mid and low rank resources)
They also looked at the big chunk of tags that were not following the power law.
  • Unique assignments. More than half (57%) of less frequently tags are used only once. They think that they can be seen as "shortcuts" for a user to a resource or a misspellings. They argue that these tags are useless from retrieval point of view (hmm..).
  • Personal vocabulary. especially in less frequently used tags (19%) of tags were only used by one user but assigned to many resources. They are useful for personal retrieval but useless for the rest of the community.
  • Unpopular vocabularies. between 1/5 and 2/5 of tags are assigned to different resources by different users only once. Unpopular vocs used by a small fraction of users.
  • they conclude that from retrieval point of view (e.g. inverted indices, TF*IDF) a large fraction of tags are good for single or sub-communities, and only the power law distributed tags are good for that.
    • They don't say anything about how to include the large fraction of tag not distributed by power law into IR methods.
Retrieval Aspects
Q: Do tags add information to further to description and title for retrieval purposes? This is a lot along the lines that I am also interested in, although I will look more into the networks of users. They say that for retrieval tags can be seen as an additional resource. Moreover, about 50% of available description contain information similar to the information described by tags, whereas the remaining 50% can be seen as orthogonal information.

Comment. This all is treating tags only as additional keywords that can be useful for conventional retrieval purposes. I think the connection tag-resource-user is more interesting. Just the fact that even if the tag is misspelled or hooks to a small user community is less important to me, because I know that the fact that this resource was tagged shows that the user has an interest to this resources, thus it is a vote. This aspect has an immense potential for retrieval (recommender point of view), but is seldom regarded in papers with very conventional retrieval approach.

Tuesday, October 30, 2007

Multilingual tags and the language of LO

I've looked into tagging in different languages before. An interesting thing came out of our little pilot: teachers, non of whom mother tongue was English, still had about 20-30% of tags in English. We had two different thoughts on this,
  • either tag is in English because teacher wanted to share these tags with other teachers, or
  • tag was in English because it is related to the language of the learning resources that was bookmarked
I was now interested in the second possibility, and took a look at a sample of 136 bookmarks with tags in multiple languages related to them.
  • The LOs were in English, Hungarian, Polish and Estonian.
  • The users (43) were Hungarian, Polish, Estonian and Lithuanian
Fair enough, all the English tags were related to the English resources! In close to 30% bookmarks (39 out of 136) this was the case (which also means that 30% of LOs were in English).

Moreover, it seems that for about 1/3 of the times the language of the LO was the same as that of the tag, whereas 2/3 of the cases it varies according to the language of the user. In about 3% of bookmarks one was able to observe multi-lingual tags.

Tuesday, October 16, 2007

New acquitance: Semiotic Dynamics

Pretty exiting, I came across this new area of Semiotic Dynamics, which is described as "a new field that studies how semiotic relations can originate, spread, and evolve over time in populations, by combining recent advances in linguistics and cognitive science with methodological and theoretical tools from complex systems and computer science." One topic of this study field is folksonomies, which draw my attention. The stuff can look like this.

Everyone nowadays repeat the same mantra of web 2.0, but somehow this project managed to say things sets it apart:

..users are no longer limited to consuming or creating online content, they also provide the semantic scaffolding holding together such content, thus taking on an active role in shaping the architecture of online information. The collaborative character underlying many Web 2.0 applications puts them in the spotlight of complex systems science,..

"Semantic scaffolding holding together .. content", that's a pretty awesome way to put it!

The paper "Vocabulary growth in collaborative tagging systems" investigates the temporal evolution of a tagging vocabulary size (of delicious) both on a
  • global level (the number of distinct tags in the entire system) and
  • local level (the growth of the number of distinct tags used in the context of a given resource or user).
It asks questions like how does the number of tags grow?; what is the rate of invention of new tags? is the asymptotic number of tags finite (uugh, a nice way to say it)? etc...

The paper finds out that the growth behaviours are remarkably regular throughout the entire history of the system with power-law behaviours with exponent smaller than one (non of that "fat head and long thing tail"!) and across very different resources being bookmarked.

Moreover, they find that there are some intrinsic characteristics of the system which do not depend strongly on the size of the dataset, like that the average number of tags is about 3.4 (local level). If I get it all right, they conclude on this that on the local scale (resource or user) "all curves tend to lie along a "universal" growth curve with an exponent close to 2/3".

The authors of this paper also highlight that the tools and concepts from complex system science may prove valuable for understanding the structure and dynamics of folksonomies.

Some interesting papers towards this direction: http://www.furl.net/members/vuorikari/semiotic_dynamics

Thursday, September 27, 2007

Some thoughts after SIRTEL07

Last week the SIRTEL workshop took place. The papers are found here and the slides, well, most of them, at the EC-TEL07 conference wiki. I have pretty good feeling about the workshop, it was one day long, we had about 20 people participating, some of whom chose to stay with us for the whole time, and some who were hopping between workshops. For me that is totally fine, we all are responsible for our own learning! Especially in conferences where many parallel sessions are running, I would encourage people to try to get best out of them.

For those who could not make it at all, you can soon find recording on the SIRTEL site.

The workshop had four main sessions:
  • We started with a keynote address from people who work with music recommenders. MyStrands people talked about applying social recommender systems to technology enhanced learning. It was an interesting talk that challenged all of us to think what are recommenders for learning purposes in the first place (goal) and what kind of data do we want to use to do that.

    As any good keynote, this one gave more ideas to think than answers. It nicely set the base for the further discussions during the workshop that focused on the need to define the field of Social Information Retrieval for Technology Enhanced Learning, and to establish a baseline so that we know what are we really set to do.

  • The second session was about Tagging and Visualisation. We had my presentation about the user behaviour on tagging in multiple languages; then there was a presentation from COSL that talked about "Activities of Daily Living on the Web", Brandon also showed a few demos of the widgets that can be used to rate or recommend related content. That was followed by a talk on reward structures to encourage teachers to share open educational material. Finally, we listened about Visualisation of social bookmarks, a work that leads into visualising bookmarks in an educational repository.

  • The 3rd session was on Recommender Systems. Here we first heard about some R&D work that OU NL is carrying out using the idea of learning paths to better support learning activities of students. Then, there was a study about using affiliation networks as a mechanism for collaborative filtering (understood largely). This was followed by a study on simulating recommendations based on multi-attribute ratings on learning resources by teachers. Finally, we had a system demo of Daffodil that supports collaborative information seeking.

  • The final session was what we called "Enablers and Challenges". It was a discussion session, and as we advanced, it was clear that people had a lot to say. It might even have been better to allow more time for this, but hey, you live and you learn.
I try to sum-up, but basically it illustrates the main topics that we talked about. If you look at the left side, there are the fundamental questions:
  • How to define and chart out the area of Social Information Retrieval (SIR) for learning?
  • Is this application domain different from other SIR, on micro and macro level?
  • What do we recommend?
  • In what context?
  • and based on what?
On the right hand, there are the issues related to implementation and evaluation of it. These are:
  • What are the best SIR methods for TEL?
  • And what is the data that we should use? The "data issue" was something that was heavily emphasised by the MyStrands folks, who obviously speak of experience.
  • The questions rouse also: when do we start implementing these for real or are we just over-engineering and never ready to launch?
  • Evaluation and empirical data for real evidences was on the focus a lot.


More will follow. This is quick and dirty now, hopefully I will get more input from people participating in order to get more depth on our summary.

Sunday, September 16, 2007

SIRTEL'07: la raison d'etre

"We use people to find content. We use content to find people."*

On Sept 18 our SIRTEL workshop takes place. It's gonna be "Serious Fun"! Let me just outline why:

SIRTEL'07: Raison d'etre

Recommender systems, as well as social navigation, have been around since the popularisation of WWW, that's some 15-20 years now. The idea is to help people choose the right stuff from a potentially overwhelming set of choices. To facilitate that users could be helped with information from other users, the choices made before (by themselves or similar users), the ratings or reviews other people had done, etc. (Rescnik et al., 1997)

The field of learning technologies has seen recommenders of some sort being discussed and prototyped since the late nineteens. In the review of the field in Manouselis et al (2008) we identified about 10 recommenders, and even more conceptual papers of them, but very little has matierialised so far.

Since the last few years recommenders have made a second arrival into the discussion topics of technology, or network, enhanced learning. Undoubtedly, this has been influenced by the arrival "Web 2.0" with all its ideas:

- Collaborative tagging, for example, has changed lots of ideas of how metadata should be produced and how static a metadata record should be: it's not anymore one metadata record produced by a librarian, but lots of annotational and attentional metadata by lots of users.

- Other annotations by users that express their subjective judgements have seen a huge growth too, we don't only talk about ratings or reviews in their traditional sense, but also tumbs-up or down, giving pokes to people or objects, etc.

- Social bookmarking, which allows users to create easy references to their own collections of digital resources (photos, books, links, music,..), has given a new dimension to the concept of social navigations. The link between resource-user(-tag) allows users to navigate other people's collections and thus find novel resources. Also, the same resource-user-tag link gives researchers an itch to use this information to group similar users for recommendation purposes, as well as to study the emerging networks.

- Expressing social ties between people has also brought new possibilities along. We are not only seeing networks of friends, but there are new possibilities where people can express different networks, ones for professional use, others for personal, recreational, etc purposes. Also, portability of these networks has become an issue discussed for better designs (social-network-portability group, PeopleWeb ,..).

- Something else is also happening behind the scenes. Clicksteam and user behaviour on the Web is not anymore a property of the commercial portal on which users are, but users are starting to take seriously how their "attention" is being used, who owns it, etc. Attentional metadata is a huge source of information that educationalists are also starting to take more seriously and thinking how it could be used for better serving learners and teachers (Contextual Attention Matadata, Attention Profiling Mark-up Language, Attention Trust,..). Attentional metadata can also become crucial when it comes to better understanding the intentions of a user, why are they, for example, looking for some information and for what task at hand!

- Finally, content for educational use, or rather its production, is also seeing a change. Users generate more and more of the content on the Web in general, a trend which is also seen in the e-learning. Of course, traditionally teachers have always produced lots of their own material, but now its re-use also has been facilitated (e.g. repositories/referatories). Also, the collaboration aspect is facilitated by the Web, it has become easier for people to work together on things (e.g. wikis, collaborative platforms,..). Additionally, learners produce plenty of material which also should be seen and used as educational content.

To sum-up: two main topics evolve around social context and social content. Social context is how we express the who, where and with whom, and social content are the objects or digital artefacts that are in the center of the communication, exchange and networks.

All the above has hopefully also changed how we will see the future of social information retrieval for technology enhanced learning. This workshop will all be about that! Serious Fun!

-------

N. Manouselis, R. Vuorikari, F. Van Assche, “Collaborative Filtering of Learning Objects for Online Communities: An Experimental Investigation”, accepted for publication in Computers in Human Behavior, Special Issue on ‘Advances of Knowledge Management and Semantic Web for Social Networks’, 2008.

P.Morville, 2004

Resnick P. & Varian H.R., “Recommender Systems”, Communications of the ACM, 40(3),1997

Thursday, August 30, 2007

More thoughts on multilinguality and tags

Lately I've been thinking more about tags and how the fact that users use them in different languages effect on the tagging system. In the case where I work (EU+education) we want to use tags in different languages as something that unifies people rather than divides them in different sections. That is why in our system we are NOT thinking of keeping multilingual tags and other annotations separated.

This type of separation along language and/or national lines can be seen in quite a few places on the Web. For example in Amazon, the reviews and ratings are not shared between the .com and .fr version. I understand that reviews and ratings, especially from experts and authoritative reviewers, are something really culturally biased, but I would think that it is interesting for readers in the US to know how a book has been received in France.

Lately in our team we've also talked about translating tags. Like if my tags, which I have added in English would be translated by someone, or a machine, into Finnish, French, etc. I don't like that idea. If I translate my tags, for example I add a tag in English and in Finnish, it's fine. But if it is done for me, I don't think it Ok. Let me explain:

I prefer to display to users only USER generated tags, not translations (neither people done nor automated ones). The key thing with tags, and the big difference compared to normal vocabularies, is that they not only describe the resource, but are associated to a user. This relation of users, tags and resources is fundamental!

In the scenario where tags are translated the following questions arises: to which user do you link a translated tag? In my opinion (say, if pushed to an edge), if a tag is translated, it ceases to be a tag and becomes just a mere keyword.

The above does not mean that tags could not have translations or equivalent terms in other languages or in its own language. Most likely in our system we will see lots of both. But the difference is that those tags all are created by other users and can be associated to users and resources. Translated keywords can be only associated to resources. This connection of users, tags and resources becomes our main asset for connecting people across the national and linguistic borders. Let's keep it that way!

If tags are translated, they could be used for other purposes than for displaying (I mean tag clouds, social navigation, etc). Translated tags could, for example, be helpful as keywords to make the search better. If a tag is translated, it should also be indicated in the metadata of the tags.

Saturday, August 04, 2007

Draft paper: Analysis of User Behavior on Multilingual tagging of learning resources

This is an almost final draft of a paper that I'm currently working on. It's been accepted as a full paper to the SIRTEL workshop.

Ah, should be mentioned, maybe, that I'm also co-chairing it :) It's gonna be very cool, so try to make it there, if possible.

If not, you can always think of posting a question in YouTube, like they did in the US presidential campaign. I kind of like that, although I don't think that I get CNN to co-host it!

Anyway, comments are welcome on this on. All images are missing, I was testing Google docs for this-copy and paste from OO did not include images.

Also, the formating took some damage, sorry about that. The final, more readable version will be at the conference site in about 10 days.

Analysis of User Behavior on Multilingual Tagging of Learning resources
Riina Vuorikari1,, Xavier Ochoa2, and Erik Duval1


Abstract. Although social, collaborative classification through tagging has been the focus of recent research, the effect of multilingual tags is often overlooked. This work presents an early exploratory study of the production and consumption of multilingual tags in a European educational K-12 context. The data, produced by teachers bookmarking and tagging learning resources during three month period, was analysed. Thereafter, this information was presented in the form of metadata keywords to a focus group of teachers who evaluated its descriptiveness, usefulness and overall quality. The results of this early study suggest that users are divided about the benefits of multilingual tags, however, some tags are useful for some users, thus “hiding all but the right tags” becomes crucial for the success of a multilingual collaborative tagging system.

Keywords: Collaborative tagging, multilinguality, learning resources.

1 Introduction
The use of social, collaborative classification systems has gone through a continuous growth in the latest years [1]. An example of this is a multitude of sites that provide some type of social annotation of digital artefacts and a social navigation system (Flikr, del.icio.us , CiteULike, Last.fm, among others). Social tagging, i.e. allowing individuals to apply free text keywords to digital objects, potentially offers advantages in terms of personal knowledge management, serendipitous access to objects through tags, and enhanced possibilities to share content with emerging social networks.

Several studies have been undertaken to better understand the behaviour and evolution of social tagging systems. Early research has been conducted by Mathes [2] where the term “folksonomy” is used to compare the emerging socially generated vocabulary with the more formal ontology concept. Golder and Huberman [3] first looked at user patterns of collaborative tagging systems. Recent studies focus on the navigability of such social systems [4] and on understanding the network properties [5].

A prevailing aspect among current studies concerning tagging is that they assume that tags are represented in a common language [6], understandable by all the members of the user community. Guy suggests that it is not always the case [7], but does not offer insight on how to deal with tags in multiple languages.

Lately, multilingual tags have started emerging on popular social tagging systems as their user-base grows, and different ways to deal with multiple languages can be observed. Delicious users, for example, add tags in different languages for a bookmark (e.g. achat, shopping) and even in some occasions add language identification in tags (e.g. lang:fi) for the language of the resource. However, it does not offer any system level support, that allows users to see tags, say, only in French or Finnish. Other services, like Yahoo!'s MyWeb on the other hand, offer tags and tag clouds in different languages in their localised parts of the portal (e.g. .fr, .es, ...), thus some language identification of tags takes place on the system level. Thirdly, In LibraryThing experienced users can combine tags, where in some occasions tags in different languages have been grouped together.

Our work, still at its early stage, attempts to shed light on a community of users who shares a common educational interest to use a social tagging system across country and language borders, but does not necessarily share a common language, as the users are free to choose the language(s) in which they apply tags. This exploration takes place in the context of two European Community founded projects, CALIBRATE1 and MELT2, both focusing on sharing and re-using of digital learning resources for K-12.

European education, especially that of K-12 education, is inherently multilingual and multicultural. Offering educational resources and services in native languages is deemed important, but equally important is the exposure to other languages. One way to promote this is to make learning resources available across national and linguistic boarders. This puts constraints on semantic interoperability, i.e. how well content and its metadata can be understood by other systems and users.

Controlled vocabularies, such as multilingual LRE Thesaurus3, can be used to overcome some hurdles of semantic interoperability. However, the gap between the terms used by experts and practitioners in the field is also problematic. For that reason, the current research looks into co-existence of taxonomies and end-user generated tags.

A federation of learning resource repositories in a multilingual context needs to support multiple languages at the system level in order to support each repository and its national user-base, but at the same time, there is a need to allow people (i.e. user information and preferences), resources and tags to “travel” across national and linguistic borders.
This paper is structured as follows: first, in section 2, we analyse the early stage of the bookmarking and tagging behavior of our community in order to better understand how teachers bookmark and tag resources in a multilingual context; what types of tags are provided and in which languages. Then, in the section 3, an experiment is presented that measures the effect of multilingual tags on the descriptiveness, usefulness and overall quality of the metadata. Finally, the findings are discussed and applied to design decisions for multilingual tagging systems.

2 Analysis of tagging behaviour in multilingual context

The CALIBRATE project makes K-12 digital learning resources available to its pilot schools (78 schools ) in Hungary, Austria, Estonia, Czech Republic, Lithuania and Poland in their different curriculum areas. Schools can access material in different languages through a portal that is connected to a federation of learning resource repositories [8] in the pilot countries.
As part of the project's multilingual search interface4, a personal bookmarking and tagging tool has been available since the beginning of 2007. This tool allows a user to create personal collections of learning resources by bookmarking interesting resources found through the portal. To facilitate the management of these personal collections (also called favourites in the project), the user can also add keywords to resources to make it easier to ”keep found things found”. These keywords are free for the user to choose and can be expressed in any language. The collections and keywords are kept private to the user, and at this stage of the experiment, they cannot be shared among users.

The data for this analysis is from a period of about three months (January 24 to April 21 2007). There were 77 teachers who made 459 bookmarks with 417 multilingual tags on 320 different learning resources. It is intended to have regular analysis of this data within the projects lifespan (-2008).

2.1 Quasi-Experimental Set-up

A total of 173 subjects used the portal during the time of the experiment, however, the subjects of this dataset comprises of a group of 77 teachers who had done at least one bookmark during this time. Thus, it was a self-selected group formed based on the bookmarking behavior during the period of three months and it represents 45% of all the pilot participants. As there was no overall methodology to introduce bookmarking and tagging to the subjects, more than half of the participants had not shown interest in using this feature of the portal.

The bookmarking habits, at this very early stage, varied a lot in terms of what languages to use, how many tags to add, how to add multiple tags (with comma separated or without commas), etc. Also, hardly any of the participants had previous experience on tagging, so not one single tagging convention emerged, rather many different ways to use tags in multiple languages. As there is very little research done on the multilingual context, we think it is important to study the early stage of tagging behaviour to better anticipate the effect of multilinguality on the system to improve its design.

It is noteworthy to mention that the bookmarking and tagging system, at this stage of the pilot, offers very little social influence in what comes to choosing what to bookmark and what keywords to choose. Oftentimes in social bookmarking sites, social cues are made available (e.g. most bookmarked items, tag clouds, tags are recommended based on previous tags, etc). At the time of the experiment, the system had hardly any tags attached to resources, so teachers started from an empty plate. In the case where a resource was already tagged by another participant, the user would see the term(s) only if they were in the same language as the interface is.

2.2 Results

In the part we present the results of the analysis, which will be discussed further in conjunction with the other results in the discussion section.

When we look at the distribution of bookmarks per users, we can find that on the average, each user had 6 bookmarks (Fig.1). However, the distribution was very wide; 10% of the users had more than the average amount of bookmarks, which leaves 90% under the average. Eight of the users could be called “super users”, as they had more than 20 bookmarks, and 12 users had between 20 and 6 bookmarks. About 30% of the users seem to have only experimented with the bookmarking system, as they only have one single bookmarked item in their favorites folder.


We had recorded 418 tags in the system. During the semantic analysis of tags we found that many tags actually contained multiple terms, i.e. they were bundles of terms without comma separation. This was due to a technical feature of the tool that treated terms without comma separation as one tag. When broken down, they resulted in 585 terms. They were translated into English and a semantic analysis was performed to better understand the types of tags. We used the classification from Sen [9] that is also based on the categories of Golder et al. [3], which are Factual tags (Golder: item topics, kinds of item, category refinements); Subjective tags (Golder: item qualities) and Personal tags (Golder: item ownership, self-reference, tasks organisation)

The vast majority of the tags at this early stage (Table 1) are of the factual type. From the factual tags, 79% were put into a rough category of topic and 14% of the category refinement with richer information. The rest of the tags were subjective in their nature and could be used to describe the quality of the resources or how the person felt about them. None of the tags fell into the category of personal tags as Golder describes them (e.g. tags related to item ownership, self-reference or personal tasks organisation). When we analysed how these tags were used and re-used among users, we found that 80% of tags related to bookmarks were factual and 20% of tags subjective tags. In a MovieLens study [9], for comparison, the distribution was 63% factual, 29% subjective, 3% personal and 5% other.
Table 1. Types analysis of each tags (no re-use)
Factual
340
93%
Topic
Category refinement
288
52
79%
14%
Subjective
24
7%
Personal
0
0%

After categorising the tags, we further studied their nature. Two main trends seemed to emerge, first, many of the tags contained the same terms as in the title, i.e. user had just copied the title in the tag field. Second, about 13% of tags contain a general term, a name, place, e.g. EU, Euroopa, Euroopa, Europa, europe, geograafia, Phytagoras, etc . We hypothesise that this type of “travel well” tags, even if not translated, could be found useful for other users for their close similarity in spelling in many languages. We think it could be of interest to work towards automatically filter this type of terms from the pool of all multilingual tags, for example, by matching them against existing multilingual vocabulary lists available on the Internet.
When we looked at the number of tags that users related to bookmarks, we were able to identify some early trends. For the total of 459 bookmarked resources, we found that some of the tags were re-used, there was an average of 1.92 tags/resource. More than half (56%) of the tags were entered as a bundle of terms, i.e. most teachers had added 2 to 6 terms without a comma separation. In quite a few cases these terms were comprised of the terms in the title of the resource (Fig.2). In 28% of the cases only one term was entered as one tag.

The rest had used multiple separate tags (2-6 tags). In the latter case the terms were not necessary related to the title alone, but carried other types of information (e.g. title: Umweltkids and tags: Oekologie, Artenschutz, Regenwald, Tierschutz, Skisport).
Contrary to our expectations, the users took liberties to add tags in multiple languages and to use the portal interface in different languages than that of their mother tongue (interface was made available in the languages of the pilot and in English). This made the identification of the language of tags more difficult, as we had expected to be able to identify the language of the tag from the language of the interface that the user used when inserting the tag. In about 70% of the cases we were able to identify the language of the tag correctly using this method, which leaves us with a 30% error rate on language identification. This error in identifying the language of the tag correctly would make it hard, for example, to display tags and tag clouds in one single language, an issue that is related to the usability of the portal, and the one of which the second experience was set up to find more evidence.
We found the following scenarios for tagging, however, due to our logging, we can't give percentages for these use cases:
  • Interface and tags in mother tongue
  • Interface was used in mother tongue, but tags in other language
  • Interface was used in a language that is other than the mother tongue, but tags were entered in mother tongue
  • The tagging language was other than the interface language and the mother tongue
These scenarios were found through comparing the real language of the tags to that of identified language by using the interface language. In this early stage of the experiment it is impossible to draw firm conclusions, but it seems that users are likely to use, or at least try, the interface in different languages. We found, for example, that the tags entered through the English interface were in English only in 50% of the cases, which means that users added tags in languages within their areas of competences. On the other hand, we also found that there were many more tags in English than we expected from the choice of the interface language. These users had chosen to tag in English, even if they used the interface in some other language, most likely to be able to share tags with users from other countries.

3 Experiment with Multilingual Tags

An exploratory experiment was set up in order to measure the perceived usefulness and quality [10] of multilingual tags, traditional metadata and expert classification keywords. We were also interested in how users reacted when they were confronted with tags in multiple languages that they did not have knowledge of. The experiment subjects were shown a list of learning resources metadata with keywords in multiple languages, the list was imitating the search result list of the portal. The results of this experiment will be useful to guide design decision in the development of retrieval tools for learning objects in a multilingual environment.

3.1 Experimental Set-up

Thirteen teachers, who belong to the MELT focus group, were selected to participate in the experiment. They were confronted with metadata regarding five learning resources in different areas of primary and secondary education curricula, namely in health education, social science, physics, mathematics and biology. An online form was used for the experiment5.
Each learning resource had a metadata description, but the number of elements varied. However, they all had the following metadata: title, description, age range (all in English) and keywords. The keywords were comprised of tags and thesaurus terms, they were mixed together and displayed in an alphabetical order. The number of Thesaurus terms and tags varied for resources. Twenty of these keywords were thesaurus terms in English that an expert cataloger had used to classify the resource. The rest (39) were multilingual tags provided by pilot teachers during the three first months of the CALIBRATE pilot. These tags were both in commonly used languages and in less used languages as listed below:
  • 11 in Hungarian
  • 7 in German
  • 7 in English
  • 6 in Polish
  • 4 in Estonian
  • 1 in Finnish
The participants were asked to look at each learning resource at the time and go through the metadata related to it. Then, they were exposed to two different task related questions: first, to select the keywords that they found helped them to learn about the resource for the given learning resource (i.e. descriptiveness), and secondly, they were asked about decision support (i.e. help using the learning resources in teaching). Finally, they were also asked to rate the perceived overall quality of all the metadata displayed (traditional metadata plus keywords). This procedure was repeated for each one of the five learning resources.

Once the review of all the resources was concluded, the users were asked to identify their language competencies, and to indicate their comfort level when keywords were presented in languages that they did not understand. All these questions were mandatory to answer. The subjects commented later that in some cases they did not feel that any of the keywords was useful, but they had to choose one to conclude the web-survey. This might have skewed the results to some extend. Finally, participants had a choice to leave free comments about their experience during the experiment.

3.2Results

In this part we present the results of the experiment, which will be discussed further in in the following section.
On average, only 35% of the presented keywords, both Thesaurus and tags, were found descriptive for the learning resource. The thesaurus terms were found descriptive in 58% of the cases, while the tags only in 25% (Fig.3). When we look at the two top terms for each resource, we find that Thesaurus terms were somewhat more popular (60%) than tags (40%) (Table.2). All but one of the most popular tags were in English, which was also the most spoken language among the focus group. There were a lot of variations, by resource and by language groups, on how users perceived the keywords.

For example, for the first resource in the Fig.3, there was only one Thesaurus term and nine tags, which were in English and German, the languages widely spoken by participants. In this case two of the tags were chosen almost as often as the Thesaurus term. As for the second resources in Fig3, there was almost equal amount of tags and Thesaurus terms; two tags, both generic terms (EU, Europa) were chosen more often than Thesaurus terms.


Fig. 3. Percentage of tags and thesaurus terms found descriptive

The no:3 in the same figure represents a case of multilingual tags in less spoken languages in which the users did not have competences in. In this case two Thesaurus terms were most chosen, however, two “travel well” tags (JavaApplets, Applets) were very high on the list. As for the resource no:4, there was an equal number of tags and Thesaurus terms which was also displayed in the results, top two positions were held by both. In the last case the tags were in less spoken languages, in Hungarian and Estonian; one Hungarian tag was found useful by all with Hungarian skills.


Table 2. The two most popular keywords for each resource

From the total number of keywords, 54% were in a language within users competencies; however 87% of the keywords found descriptive were in a language that the user had skills in (Fig. 4). The remaining 13% of tags that were found useful, but not in the languages that users had competences, seem to comprise of terms of the generic type, the “travel well” tags, as described previously.

Fig. 4. Percentage of keywords in a known and unknown language that were found descriptive

When we asked about how well the keywords would help to use the resource, in average, only 27% of the presented keywords were found useful to indicate possible uses of the learning resource. Thesaurus terms were found useful 50% of the time, against only 18% for tags. In this case, when we look at the languages in which the participants had skills in, we find that in 83% of the time they mark those terms useful.
We can say that the issue of multilingual tags evokes sentiments and also splits users. From the thirteen users, two “love” being able to see multilingual tags and four found them useful, whereas six found them confusing and one “hates” to see keywords in languages that he/she does not understand (Fig. 5).


Fig. 5. Answer of the participants to the question: “What do you think when you see the keywords in many languages?”

Lastly, we were also interested in how users evaluated the overall quality of the metadata record [10]. The quality assigned to the metadata record correlate in a statistical significant way with the amount of words in the description (.909) and with how descriptive (.944) and useful (.994) the user found the keywords for that learning object. The first correlation was already found in a previous study [10].

4 Discussion on the results

The main argument that comes out of this early experimental research is that certain multilingual tags seem to be useful for some users – the challenge is how to make the other tags invisible? Moreover, the results can lead us to discuss the multilingualism of tags and indexing keywords from different perspectives; what are the user needs and requirements in a multilingual Europe, how can they be supported at the system level, what are the ramifications on their usability and how is the overall quality of the portal enhanced through multilingual tags?

In the spirit of “how to hide all but the right tags for each user”, this research has identified two topics that need further investigation: one is that of identifying “travel well” tags and the other that of how to correctly identify the language of each entered tag. After tackling these two issues, hiding all but the right tags becomes a much more manageable task.
Solving those two issues would greatly enhance the usability of the portal that offers multilingual tags: as shown in the experiment with the focus group, being exposed to tags in many languages has a dividing effect. One half of the subject expressed that they liked to see multilingual tags, whereas the other half found them rather irritating, especially when they were in languages that they did not recognise. It was also mentioned that multilingual tags make it harder and slower to pick the useful terms out of all the tags.

Two possible ways to further advance the cause could be envisaged: to automate the recognition of “travel well” tags and the identification of languages of all tags by using already existing vocabulary and dictionary lists on the Internet, or by crowd-sourcing” it to users, which is asking the end-users to identify “travel well” tags and allow them to translate and correct the language of tags. A co-existence of both could also be envisaged.
Another interesting outcome of the study is that keywords in general received a rather low appreciation rate among the subjects: 35% of the keywords were found descriptive and 27% were found helpful to the use of the resource. Overall, the Thesaurus terms performed better than the tags, however, it can be argued that tags, after all being produced with no outlay, showed an overall encouraging and potential gain in their usefulness. This needs to be investigated further and more in depth with a bigger sample size.

It could be envisaged that, in the case of sharing the accumulated knowledge regarding the actual use of resources in teaching and learning, social tagging could be in the future interesting in adding value to keywords. Thus, more design level effort is needed in guiding and encouraging users in using tags for such purposes.

5 Conclusions

This early study contributes to the understanding of tags in multiple languages. Despite the small sample size and early tagging behaviour of the participants, we can assume that tags in a multi-cultural and lingual context offer potential advantages to the collaborative tagging system and its multilingual user communities (e.g. Europe). However, there are challenges and research questions that need further attention. As it becomes clear that some tags are useful for some users, the design challenge becomes “hiding all but the right tags”. This implies for both entering and viewing the tags, e.g. what tags and in what languages to show/recommend to users when they are about to add a tag and what kind of tags to show for retrieval and social navigation.

First, it seems important that the system has a capacity to infer and identify tags entered in multiple languages, so that users can be shown or exposed to tags only in languages that they desire. Second, it appears that there are tags that “travel well”, i.e. tags that are easily understood by many users despite the lingual barriers. It appears important that those terms are identified, either automatically or by users, so that they could be better taken advantages of. The two above findings seem to further indicate that tags in different languages should not be kept as separate silos, but interaction between languages should be used for connecting like-minded people across country and linguistic borders.

The issue of multilingual tags is intriguing and offers interesting possibilities for both the learning resources repository managers and administrators, as well as for end users. In a multilingual environment such as Europe, where making learning resources available in languages others than in mother tongue is becoming more mainstream, mixing tagging with top-down expert classification system seem to offer interesting possibilities for accessing resources and for other novel educational applications that leverage the social network aspects of a given community. From this early experiment it becomes clear that further research into the topic of multilingualism is needed to better understand its complexity, but also to be able to design more adaptable applications.

Acknowledgments. We would like to thank Sylvia Hartinger from European Schoolet for making the tags available for analysis and Jim Ayre from Multimedia Ventures Europe Ltd. for valuable comments. Acknowledgment also goes to Helsingin Sanomain 100-vuotissäätiö for the research grant that made this research possible.

References
1. Marlow, C., Naaman, M., Boyd, D., Davis, M.: Position paper, tagging, taxonomy, flickr, article, toread. In: Collaborative Web Tagging Workshop at WWW2006, Edinburgh, Scotland. (2006).
2. Mathes, A.: Folksonomies-cooperative classification and communication through shared metadata. In: Computer Mediated Communication, Graduate School of Library and Information Science, University of Illinois Urbana-Champaign. (2004)
3. Golder, S.A., Huberman, B.A.: Usage patterns of collaborative tagging systems. Journal of Information Science 32(2), pp. 198—208. (2006).
4. Chi, E., Mytkowicz, T.: Understanding navigability of social tagging systems. In: Proceedings of CHI. Volume 7. (2007)
5. Catutto, C., Schmitz, C., Baldassarri, B., Servedio, V.D.P., Loreto, V., Hotho, A.,
Grahl, M., Stumme, G. Network Properties of Folksonomies. AI Communications
Journal, Special Issue on "Network Analysis in Natural Sciences and Engineering",
2007.
6. Hammond, T., Hannay, T., Lund, B., Scott, J.: Social bookmarking tools (i). D-Lib Magazine 11(4) (2005)
7. Guy, M., Tonkin, E.: Tidying up tags. D-Lib Magazine 12(1) (2006)
8. J.-N. Colin and D. Massart. LIMBS: Open source, open standards, and open content to foster learning resource exchanges. In Kinshuk, R. Koper, P. Kommers, P. Kirschner, D. Sampson, and W. Didderen, editors, Proc. of The Sixth IEEE International Conference on Advanced Learning Technologies, ICALT'06, pp. 682-686, Kerkrade, The Netherlands, July 2006.
9. Sen, S., Lam, S.K., Cosley, D., Frankowski, D., Osterhouse, J., Harper, F.M., Riedl, J.: tagging, communities, vocabulary, evolution. In: Proceedings of the 2006 20th anniversary conference on Computer supported cooperative work. pp. 181–190 (2006)
10. Ochoa, X., Duval, E.: Towards automatic evaluation of learning object metadata quality. In: Advances in Conceptual Modeling - Theory and Practice, ER 2006 Workshops BP-UML, CoMoGIS, COSS, ECDM, OIS, QoIS, SemWAT. pp. 372–381. Lecture Notes in Computer Science, Tucson, AZ, USA, Springer (November 2006)