Friday, December 19, 2008

How different is user behaviour on a portal from the ones who log-in to ones how do not?

I've recently done quite a few studies on users of learning resources portals, I've looked for example how do they tag resources in a multilingual context or how much use and reuse is there across the borders. In all cases the studies have concentrated on the small amount of the (minority) users who actually log in and had created Collections of resources: in Calibrate that was about 30% and in LeMill about 10%.

Now in MELT we've revised the logging scheme to collect the click-stream from users who don't log-in. We also have Google analytics, but I don't have those at hand right now. I looked at the data from last 3 months, from Aug 18 to Dec 18, and then only from the last month (Table 1).

What do users do on the portal?

The most popular activity on the portal is search, 64.29% of all actions on the portal are different types of searches. They result in "playing" the resources in 18.31% of all actions on the portal. 13.09% of all actions are contributing actions on the portal, this means adding a tag, bookmarking or rating it. The figure of contributing actions is actually a bit distorted, we count each tag, rating and bookmarking there. As each bookmark has average of 4.3 tags attached to it, it brings up the figure. Actually, the number of actions that contribute to "acting with an individual resource" is around 4.3% of all actions (i.e. add rate and bookmark). Other includes activities like view evaluation, view other users who have bookmarked the resources, etc.

Table 1


The downside here is not having the stats from Google analytics, so I cannot exclude our internal usage, which I know has been quite a lot, since we've been testing the portal internally. So the figures might be somewhat distorted...


What about users who log-in and the ones who don't?

About a month ago I invited some 260 teachers on the portal, so I was intrigued to see what had happened. 2 weeks ago I checked that 11% of these teachers had started their own account. But, it seems like much more have come about and cruised around the portal.

Table 2 presents the data from the last 4.5 months (Aug-December) where I have divided it in two slots: first months include pilot teachers and lots of testing, in the table it's erroneously called "First 2 months". The second slot covers the time from Nov 18 to Dec 18 when we invited the new teachers (Nov 18/19 in 4 different patches of invites). It is called "the 3rd month" in the tables (again, my mistake). Moreover, the top half of the table has data regarding users who log-in and the bottom with users who did not log in.

I have mostly the same attributes for both, how did they search; advanced, browsing by category and by tag cloud and how many resources they clicked on (play). The table also contains the number of sessions and number of actions. A session is one consecutive event when the user does something, it's logged. If left idel, the user is logged off in some time. An action is anything, a search, a click on a resource, on a tag, etc. Additionally, we have the contribution by logged-in users, these are tags, bookmarks and ratings.

Table 2


As you can see, most of the sessions (above 86%, the second last row) in both slots take place when users are not logged in. Actually, the percentage of sessions stays pretty regular in both slots. Moreover, regarding the actions, we can see that during first months they mostly (70%) came from non-logged in users. However, when we invited the new teachers, we see 10% increase in actions by logged in users (from 30% to 40%). That's positive, as it shows that some of the invited teachers were motivated to contribute.

There is actually quite big differences in what do these two groups of users do when they are on the portal. Where logged-in users spend about 1/3 of their actions in searching, non logged-in users spent about 2/3 of their actions in searching. Chart 1 shows this clearly, however, I must say that most likely the disparity between the number of searches and plays by non-logged in users in the first months are due to our internal testing. If you compare that to non logged-in users in the 3rd month, you see that there is already less searches and more plays.

There has been a difference since the new comers (3rd month): within the logged in users, the number of searches executed has gone down (10%), whereas the number of plays has gone up (from 17% to 23%). Among non-logged in users there is the same 10% drop in searches, but plays have gone up by 10% (from 16% to 27%)! That shows that the new comers were interested in seeing what kind of resources were out there in the portal.

Chart 1 can maybe be used to illustrate

Chart 1


One difference can be observed in how differently these two groups seem to search: with logged-in users the advanced search seems to be the more popular way to search (more than 50% of searches are advanced), whereas with the users who are not logged-in browsing (both by category and tag cloud) is more popular. During first months 54% of searches were browsing, which went slightly up (to 56%) during the 3rd month. The tag cloud was the biggest winner in both groups (logged-in and not) at the cost of advanced search. I assume the difference is due to the fact that people who are not logged in are interested in seeing what is out there and browse around to discover learning material.

In any case, if we look at the figures of non logged-in users within the 3rd month, it's intriguing how equally the searches are distributed across these different ways of searching. We'll keep an eye on this in the future (e.g. when we know that most non-logged clicks come from us testing the portal).

Consumers and contributors

In Table 3, where I again have data for users logged-in and not, and by periods of first months and the 3rd month, we see that when users are logged in, they do things differently. First of all, the logged-in users spare much smaller percentage of their actions in searching (average 33% to 75%), however, bizarrely, they still seem to "play" about the same amount of resources (around 20%).

Table 3


Within the 3rd month we see the percentage of plays growing. We can assume that the logs from the first months period are most likely influenced due to our internal testing of the portal, which often times includes making searches. We see that the percentage of plays go up for the non logged-in users within the last month (from 16% to 27%), which, I assume shows a more normal user-behaviour than what could be observed before.

This still indicates that there is lots of inefficiency when non-logged in users search: on the average during the 3rd month, for those logged-in, one "play" was a result of 1.2 searches, whereas with those not logged-in, one "play" was a result of 2.6 searches - lot of time lost in searching. From Table 2 we can observe that there was more browsing (non logged-in users 1 month), I wonder if that was the reason? Have to keep on eye at that one!

Most interestingly, 40% of actions by logged in users contribute are the ones that contribute something to the portal, they rate, tag and bookmark. Folks who do not log-in are consumers: they only search, click and leave (- which is fine too).

So all in all, if we look at all the actions on the portal, the contributing actions by logged in users amount to about 17%. Too bad that this figure did not go up in the 3rd month like some others did. Anyhow, it seems to follow the power-law of distribution (20-80), where small amount of people contribute a lot so that other people can take advantage of this work, also know as participation inequality by J.Nilsen (2006).


J.Nilsen (2006) Participation inequality: Encouraging More Users to contribute

Learning resources landscape

Learning resources come in all colours and shapes, that is for sure. They also come from all kinds of different places; repositories, portals, the web.... For a recent presentation and paper, I created this diagram to better depict the learning resources landscape. As I later had to remove this part from the paper to save place, I post it here.


Teachers use a plethora of ways to discover educational content online. Harvey et al. (2006) report on search strategies of 4500 US faculty members where Google-like searches are by far the most prominent (81%), second most important being own personal Collections of resources and also “portals” that provide links to disciplinary topics (55%). In our user group comprised of 45 language and science teachers in K-12 education, such diversity of strategies was also discovered: one third use national and regional educational repositories as their primary source of educational content, 28% use search engines, 21% said they create their own content, 7% use content from schoolbook publishers and 12% reported all of the above (Vuorikari, 2008a).

These search strategies also give an indication of the different types of resources that teachers use. Figure 1 illustrates a number of different sources of content that teachers use. First of all, on the horizontal axis we distinguish between platforms that have institutional support and the ones that are rather teachers’ community driven sources. On the vertical axis we distinguish between teacher-generated content and “other sources”. The latter encompasses a large number of providers from educational portals and repositories, schoolbook publishers to educational and non-educational sites created by a number of private and public stakeholders. This “other sources” category is essentially as large as a teacher’s pedagogical imagination is in taking advantage of the resources on the Internet.

This diagram allows us to draw a landscape for educational resources. In the upper left corner of the diagram, there are examples of institutional Learning Object Repositories (LOR), such as the ones managed by Educational Authorities (e.g. Learning Resource Exchange for schools and members of EdReNe) and other repositories that make educational content available. On the lower left corner we place initiatives like MIT OCW which is an institutional repository that makes available teacher-generated content. The lower right corner represents teacher-generated content in a community-driven environment (e.g., LeMill), whereas the upper right hand corner represents content that is found on the Internet from various sources and saved in community-driven environments like delicious.com. None of these boundaries are fixed and there are many in-between-models (e.g., LOR with both user-generated content and institutional ones). Our data sets for this study, which are presented in Table 1, cover a wide area of Figure 1. For learning resources we use Wiley’s (2002) definition of learning object as “any digital resources that can be reused to support learning”, as they vary greatly in granularity and other qualities.

Our evidence finding focuses on teachers in K-12 education in a European multilingual context. In the Europe Union area, where 497 million people (Eurostats) live from diverse ethnic, cultural and linguistic backgrounds, multilinguality has an important role (Council of Europe, 2007). There are 23 EU official languages, 3 alphabets, and some 60 other languages are part of the EU heritage and spoken in specific regions or by specific groups (COM, 2008). Multilinguality can be defined as a situation where several languages are spoken within a certain geographical area, as well as the ability of a person to master multiple languages. 56% of EU citizens say that they are able to hold a conversation in one language apart from their mother tongue, and 28% in at least two languages. English remains the most widely spoken foreign language throughout Europe (38%), second and third place is French (14%) and German (14%), whereas 6% have foreign language expertise in Spanish and Russian respectively. Over two-third say that they language lessons at school was the way they have learned foreign languages (COM, 2006).

..................

Harley, D., Henke, J., Lawrence, S., Miller, I., Perciali, I., and Nasatir, D. (2006). Use and Users of Digital Resources: A Focus on Undergraduate Education in the Humanities and Social Sciences. Available from
http://cshe.berkeley.edu/research/digitalresourcestudy/report/digitalresourcestudy_final_report.pdf

Vuorikari, R. (2008a). A case study on teachers' use of social tagging tools to create collections of resources - and how to consolidate them. In Wild, F., Kalz, M., Palmer, M (Eds) Proceedings of the First International Workshop on Mashup Personal Learning Environments. Available from http://sunsite.informatik.rwth-aachen.de/Publications/CEUR-WS/Vol-388/vuorikari.pdf

Wiley, D. (2002). The Instructional Use of Learning Objects. Online at: http://reusability.org/read

COM(2006). Europeans and their languages. Special Eurobarometer, European Commission.

COM(2008). 566 final. Multilingualism: an asset for Europe and a shared commitment, European Commission.

Council of Europe (2007). Un cardre Européen commun de référence pour les langues : apprendre, enseigner, évaluer. Division des Politiques Linguistiques, Strasbourg: France.

Thursday, November 06, 2008

Mind those backups! - stolen laptops

Oh boy, my digital misery does not seem to be over yet! After having my home broken into and my laptop stolen, I was dead-happy that the evil-minded robber left my external, one terabite back-up hard-drive right where it was, about 50 cm away from from the laptop that s/he stole.

Now about 10 days later I'm typing away using my new MacBook Pro. I must say that I was pretty happy to have restored my "life" using Time Machine, only about a week's worth of back-ups was missing. It felt great to log-in to my own desktop, have my applications restored just like that, and just start using my laptop like nothing happened. I even pledged to always do my backups.

Then I started noticing little things. Ops, my address book is missing. My bookmarks and passwords are missing in Firefox. Then, I wanted to upload a file, and I realised that ALL MY FILES ARE MISSING! WTF?

Those files are, for sure, on the back-up hard-drive, I can access them there. But for some reason, when importing "my life" from Time machine, it omitted to import my files. Hey, big deal, at least the file structure is there..dah.

Now I'm trying to discover an easy way to do that. I am finding all kinds of not so nice things on Time machine, like this.

Ok now, time to roll up my sleeves and start digging out those files. So far this post looks promising.

As a lesson learned: mind your back-ups!

Wednesday, November 05, 2008

Power of pursuation/example/recommendation

We plan to invite about 130 teachers to the portal and I'd like to make a little experiment on this. The idea is to show two different examples of how to access and discover learning resources on the portal, and see whether that has an influence on
  • Uptake: users sign up
  • Retention: users come back
  • Different ways to discover resources (social cues vs. conventional search strategies)
  • Focus on the system (discovery e.g. clicking on resources vs. contributing, e.g. bookmark and tag, rate, etc)
The point would be to test the statement from the results reported in Harper et al (2007), where an email newsletter with manipulated social comparison made no difference to a member's interest in using the system, but it changed their focus within the system.
While subjects who received an email message with the comparison manipulation were no more likely to click on one of the links or log in to the system, they were more likely to rate movies.
There are differences, but in grosso modo the idea has similarities: In Harper et al (2007) the manipulated social information in the email concerned the subject him/herself (treatment group), whereas in my case the information would be about some other teachers that the subjects would be able to relate with (e.g. see favourites from a science or language teacher). The biggest difference would be that there is no comparison aspect of the subject's performance to the other users in the system, which was one of the central features of Harper et al study.

Study design

The randomly selected treatment group would receive an invitation with set goals of expectations on the use of the portal. Examples will be given on how to access and discover learning resources based on social navigation cues, show examples of how to browse other user's Favourites and how to access resources through a tag cloud.

The randomly selected control group will
receive an invitation with set goals of expectations on the use of the portal. Examples will be given on how to access and discover learning resources would receive an invitation where examples would be given on how to access and discover learning resources based on conventional free text search or browsing keywords
(to be reworked, just initial ideas based on tracking methods that I could use).
  • Immediate reaction: number of people who access the portal through the direct links on the invitation as opposed to the number of people who access the portal though the main page. the time these people spend on the portal on the first time and how they search, how many searches they execute and how many resources they click on
  • Uptake: is there difference between the groups on signing up on the portal?
  • Retention: on the longer run, say, within a month, do they still come back
  • Different ways to discover resources (social cues vs. conventional search strategies)
  • Focus on the system (discovery vs. contributing in terms of ratings, tagging, etc) : do people who see examples of social navigation use these methods more than the control group? are there any differences how many resources the subjects in both groups tag and rate?

Hypothesis to test
(to be reworked, just basic ideas)

hypotheses would be that subjects in the treatment group will discover more resources than the control due to social navigation cues made readily available to them. By discovering I mean that they click on these resources on the portal to view them. I also would hypothesise that the retention rate is better among the treatment group, as they get a direct access to selected resources whereas the control group has to look for the interesting resources and might get diverted there.

Relevant studies in this direction, to be completed

A study towards this direction was reported by Harper et al (2007). They study the effect of email newsletters that told the community members whether their contribution was above or below average. They report that a) previous studies has shown that information about social norms can affect contributions, e.g. people recycled more material when they were provided with information about how much other people had recycled (Schultz, 1999).


Social Comparisons to Motivate Contributions to an Online Community.
, Harper, F.; Li, X.; Chen, Y.; Konstan, J. , Persuasive Technology, 26/04/2007, Palo Alto, CA, (2007)

Using Social Psychology to Motivate Contributions to Online Communities, Ling, K.; Beenen, G.; Ludford, P.; Wang, X.; Chang, K.; Li, X.; Cosley, D.; Frankowski, D.; Terveen, L.; Rashid, A.M.; Resnick, P.; Kraut, R. , Journal of Computer-Mediated Communication, Volume 10, Issue 4, (2005)

Changing Behavior With Normative Feedback Interventions: A Field Experiment on Curbside Recycling (1999)
by P Schultz

Monday, November 03, 2008

Web 2.0 = Learning 2.0?

Last week I was part of an expert workshop on Learning 2.0. It was organised by the Institute for Prospective Technological Studies (IPTS), one of the European Commission's research institutes. They currently run a year-long study on the Impact of Web 2.0 Innovations on Education and Training in Europe. The objective is to assess the impact of Web 2.0 trends on the field of learning and education in Europe, and to propose avenues for further research and policy-making in Europe.

It was very cool to be part of this group, we were about 30 people with various backgrounds and our main job was to looked at the preliminary results of two studies. We first discussed the intermediate results of an exploratory study that seeks to identify and analyse the existing practices related to the Web 2.0 initiatives in the field of learning in Europe. For this reason, a Learning 2.0 database had been set-up where practitioners were able to report their cases. A presentation of this study is available.

The second part of the validation workshop focused on the cases studies: Case study on 'Good Practices for Learning 2.0: Innovation' and Case study on 'Good Practices for Learning 2.0: Inclusion'.

A lot of the workshop time was spent on brainstorming mode, which is something that I truly enjoyed. The point was to try to identify what would be the NEW in what was called Learning 2.0. That's pretty tough, as we hardly know what is the new thing in Learning 1.0! Here is one image of our brainstorming chart, thanks to Graham!


The most skepticism, if I could even call it that as many of us were very enthusiastic about the potential of Web 2.0 for education, was that how can Web 2.0 technologies and tool help the learning, or can they help it at all?

Lots of things could and have been listed by the proponents of Web 2.0, like personalisation, participation, collaboration, motivation, social skills, reflection and meta-cognition. Those, however, are not inherit to Web 2.0, but to any good learning!

So is there anything that makes learning with Web 2.0 so special? In contrary to encouraging reflective learning, Web 2.0 seem to promote sporadic grasshopper minds, like some current studies on multitasking suggest.

What the workshop could say, though, was that more well coordinated research on Learning 2.0 is needed to better understand its potential. One such study in this direction is the new Becta study, which is very impressive.

Some links to other literature that folks in the workshop pointed out: http://delicious.com/tag/iptsl20

Also, check out the literature reviews and other studies that have already come out of Learning 2.0 or are about to come out. There are interesting things going on!

From the Learning 2.0. site:

The rapid growth of social computing or web 2.0 applications and supporting technologies (E.g. blogs, podcasts, wikis, social networking sites, sharing of bookmarks, VoIP and P2P services), both in terms of number of users/subscribers and in terms of usage patterns leads to the fact that the phenomena are also increasingly being used in the educational field and for learning purposes. As it enables different types of learning and teaching settings (formal, non-formal and informal), it is an important driver of innovation in learning.

Description: The Learning 2.0 study will

1. Identify and analyse the existing practices and related success factors of major web 2.0 initiatives in the field of learning in Europe;
2. Look at the innovative dimension of using web 2.0 for learning;
3. Analyse the position of Europe vs. the rest of the world in terms of quantitative and qualitative use of innovative Learning 2.0 approaches;
4. Discuss the potential of social computing applications to (re)-connect groups at risk-of-exclusion;
5. Propose avenues for further research and policy-making.


Friday, September 19, 2008

Encourage lurking in conferences!

I'm always amazed how old-school these conferences are. I'm currently in Ec-Tel 08, sitting outside of the session room on the floor and listening the speech through the half-open door. I'm a lurker.
lurking in ectel08
I do not want to participate in the whole session, but I do want to lurk around because I'm half interested and there is one speaker that I want to see later. I just don't want to sit in the room and tap on my laptop.

It would be great to have a couch or a few seats outside of a session room with a screen, and hopefully also audio, to be able to properly lurk. We already know from online communities that it is totally OK to lurk, so why would we not make it also properly available in the conferences, too?

I've had really interesting conversations in these marginal places of conferences. Let's just make them happen more often! Let's provide places to officially lurk around.

Friday, September 12, 2008

Cross-boundary ranking of learning resources

Based on the idea of Interest Indicators, like social bookmarks and ratings, I've looked at the data so that we can make the cross-boundary resources better available on the MELT portal.
The aim is that we can, based on previous users' behaviour :

a) make separate "travel well" lists of resources that have a potential to cross-borders better,

b) use this information to rank resources better in the normal search result list,

c) allow users search for resources that have a good "travel well" value (e.g. give me resources in math that can cross-borders)

This is the data that I'm using (table below) and this is how I've defined cross-boundary (e.g. cross-country and language) learning resources before. Using that definition I have manually verified the number of cross-country resources. In the dataset, about 82% of resources were cross-country.


Now, we have a problem, though. On our MELT portal we do not have information about the country where the resource originates from. Dah!

This is a big blunder (in my opinion) in our Application Profile, we have not defined the country where the resource originates. We do define the provider, and the country information could be inferred from the provider, but it does not always work.

For example, one of our providers has frequently metadata about resources that do not originate from the same country!

I've experimented with the data using the information that we have on the portal, which is LOM about the resource including the language of the resource. As we also know the mother tongue of the registered users, this gives us a kick.

In the table below we can see the coverage of cross-boundary actions that we can get on resources without using any manual labour or verification of the country or language. As a base-line, with manual verification I found that 82% of the actions concerned cross-border rating or bookmarking of a resource.


The first row represents the cross-language resources (i.e. user's mother tongue is different from the resource language). Just using this information, we get about 65% of resources right, as opposed using manual checking (82%). I think it's pretty good, I'd settle for that! (although I have to look what kind of material was left out!)

The two other comparisons in the table are based only using information about users' previous behaviour. These would be:
  • rating > 2
  • bookmark
Only using information regarding bookmarked and rated resources results in a lousy coverage of around 20%. The problem is that 25% of resources bookmarked or rated are on more than one resource, the data still is very sparse.

Anyway, I want to use that information to "cross-boundary rank" the resources. As we do not know the country where the resource comes from, my work-around is based on countries where these users come from.

Here is a visualisation about resources that have been bookmarked or rated by users (see also ManyEyes link below). We can see the orange node in the middle, a learning resource called "Five Days in New York..". We see 3 edges leading out to Finland, Belgium and Hungary. This means at least one user from each of these countries has bookmarked the resource!

So, even if we do not know the origin of the resource, we know that it has users from 3 different countries. I can infer that it is a cross-boundary resource.

As most likely one of these 3 users come from the same country than the resource comes from, I will minus one country out of the total of countries: (number of countries -1)

My cross-boundary rank will be the following:
  • Count the number of ratings grater than 2 and/or bookmarks for a resource (actions). Give each action one point
  • Count the number of these users and give each user one point
  • Count the number of user countries of origin. Give each country one point and then minus 1
  • Compare the mother tongue of each of these users to the language of resource. If they differ, give one point/mismatch.
Then, count the following:
number of users + number of actions + number of cross-language x (number of countries -1)
Let's take the above resource "Five Days in New York.." as an example
  • Count the number of ratings grater than 2 (3) and/or bookmarks for a resource (5). Give each action one point. (8)
  • Count the number of these users and give each user one point (5)
  • Count the number of user countries of origin (Hungary, Finland, Belgium). Give each country one point and then minus 1 ( 3-1=2)
  • Count the number of user mother tongue (hu, nl, fi). Compare the mother tongue of each of these users to the language of resource (en). If they differ, give one point/mismatch (3).

  • number of users (5) + number of actions (8) + number of cross-language (3) x (number of countries -1) (2) = 32 Travel well value
This way you can count a value of "travel well" for each resource that users have previously interacted with on the portal. The value will always be an integer, which is important from the technical implementation point of view (in Lucine index it apparently needs to be an integer).

The down side is that we'll have a huge cold-start problem. As I said, our data is very sparse. To seed the system, I actually still manually check the new resources that users have interacted with and make a fake bookmark on them so that it looks like it has at least two users from 2 different countries. This way the resource gets a "travel well" value counted and appears on the "travel well" list and is better ranked, etc.

Of course, at the end I will evaluate how this treatment affects on users, do we, for example, see a big amount of bookmarks on these resources that I have been able to count a travel well value?

You can see a visualisation here. This is based on on user's country of origin.

Wednesday, September 03, 2008

Cross-boundary use of learning resources in LeMill

LeMill (http://lemill.net) is a web community for finding, authoring and sharing learning resources. It is divided to four sections: Content, Methods, Tools and Community. The main target audience is primary and secondary school teachers, but anyone can join. It is a wiki-like system where all the learning resources are published under open licence and can be edited by other members.

Registered users can publish learning content, and descriptions of educational methods and tools. Users can also create their own Collections of learning resources. About 10% of LeMill users have created collections (users total based on March 15 2008), this represents 188 users (data snapshot May 30 2008).

Collections are good for "Keeping found things found", the nice resources that you find in LeMill can be easily put in a collection. Another important thing is that Collections can be used to make content units or thematic lessons. Collections are actually folders that you give a name, you can make as many collections as you want.

For me the Collections tool is interesting. It's the whole thing about what content do users find interesting enough so that they want to keep it.

In Table 1 you can find the description of the data that I use for this study. I give quickly some descriptive statistics about it, and then drill into the Cross-Boundary use of learning resources. This this I mean that the user comes from a different country than the resource (cross-country) or the resource is in a different language than that of the user’s mother tongue (cross-language). If resource comes from a different country and is in a differnt language, then it's a cross-border resource. I'll give examples of this later to make it more clear.

What's in Collections?


Users had saved 1645 resources in 376 collections. There is 4.4 resources on the average in each collections. Some Collections are huge, the biggest has 82 resources in it, whereas the median is 2 resources.

When we look at how the users have used this feature, we find a wide variety of cases. Just by looking at numbers, the most active user had 94 resources in Collections, whereas the average is 8,75 resources. Median is 3, so as usual, we have a group of very active users (30% above average) and lots of not-so-active users of this functionality.

When we look at the resources in Collections, we find that there are 1387 different resources. 13% of the resources exist in more than one collection, but most of the resources (1205) are put to only one Collection. Not much of an overlap there, which is a bit surprising seen the fact that other users' Collections are public, so I can easily go and see the lessons created by others. There are nice pivotal navigational features that allow me to click on the other user's name and see their Collections. To my dismay, though, I noticed that it is not very easy to add resources from other users' Collection to mine, which might hinder the reuse a bit.

Who uses Collections?

The cool thing about LeMill is that their user-base is a total fruit bowl. There are users registered from all over, in this dataset we have 22 countries. The top number of Collections are Estonians, that's 45% of all resources in Collections. Others are Lithuania (14%), n/a (14%), Hungary (9%), and so on.

Where do resources come from in Collections?

It seems like most Estonians put resources made by another Estonian in their collections (48.5%). Then we have n/a "country" (13.2%), resources from Lithuania (11.4%), from Finland (7.5%), Hungary (6.6%), resources from Georgia (6.2%) and so on.

What about resources originating from different countries than the user? The case of crossing boundaries.

About 40% of Collection users are Cross-Boundary users (74). You can see this at the lower part of the 2nd Table above. I was able to calculate this by looking into the resources that they have put in their Collections. I found out that every fourth (419) resource in Collections crosses some boundaries, either language or country boundaries. Let's look at this in more details (Table here on the left).

1st Case are Cross-border resources: the resource comes from a different country than the user and is also in a different language than the mother tongue. 28% of the cases were like this.

Example
: a German resource from a German teacher that a Finnish teacher has put in his Collection.

2nd Case is about crossing language borders. Most cases (76%) represent resources that are in a different language than the mother tongue of the user is. Many of these resources are in English (63%) even if they are not created by an English native speaker.

Example
: Let's say an Estonian teacher has made a learning resource in English and put it in her own Collection.

3rd Case: Cross-country resource. These are resources that are in the user's mother tongue, but come from a different country. Much less of those, only less than 5%.

Example: A resource in English made by an American and put in a Collection by a Canadian. Or it could be a German resource added into a Collection by an Austrian teacher.


So are there any commonalities in this?


In LeMill, it looks like most cross-boundary actions (i.e. resources put in Collections) are within users' language skills (lower part of the Table on the left). You'd be surprised to learn the language skills these teachers have! Most of them have one additional language on top of their mother tongue, but many of them boast 3 or 4. This results that most of the 352/419 cross-boundary resources in collections are within Foreign language skills of these users. That's 84%.

Naturally, one is curious to know what those remaining 16% of resources are?
Actually, a bit disapointingly, there were little surprise (and very little of evidence on my last post on "Vygotsky's psychological tools". Many of these resources were in English, most likely the user had forgotten to mention that s/he masters this lingua franca. Remaining were either with no text or multimedia, some resources I was not able to locate in LeMill anymore. I put some of them in my Travel Well Collection.

Tuesday, September 02, 2008

Emerging search patterns on learning resources

I am hugely inspired by the stuff from J.Feinberg and D.Millen, especially by the studies that they've done on doger, the IBM internal social bookmarking service. I must admit, though, that I had missed on it a bit, I cannot believe! Anyway..

This paper is really interesting, Social bookmarking and exploratory search (2007), not least for the reason that it offers a very interesting, almost similar study design that I am planning on my log files and search pattern analysis on the MELT portal. (Great minds think a like ;p yeah, right..)

The study design is a field study of a social bookmakring service in a large corporate (IBM) with quantitative data (click level analyses of log files and boomarking data) and qualitative data like interviews.

And, this is the data that I collect for my study (Table 1). Quite simlar!

They use a categorisation of search that I will adapt to my usage:
  • Community browsing (Examining bookmarks created by the community. In my case these could be lists of most boomarked items, travel well; tags; other people Favourites)
  • Personal search (Looking for bookmarks from one's own personal collecction of bookmarks)
  • Explicit search (Explicit search using traditional search box)
A few days ago I looked at the first logs from Melt. Here is the run-down. I have not used the same types of searches, but I will explore them for the later usage. But basically what you can see:

There were 512 search events:
  • 41% Explicit searches (adv. search)
  • 34% Community browsing (tagcloud)
  • 25% browsing categories
What was called "click-through" in this paper is when the particular navigation path resulted in a page view. This is what I call view resources. We can see that there were 538 page views, which implies that most likely users have clicked on more than one resource as a result of a search.
  • 74% of resources were viewed in search result list (srl), this means that they were results from advanced search and browsing categories

  • 20% of resources were viewed as a result of community browsing (e.g. tagcloud, lists)

  • 5% of of resources were viewed as a result of personal search (e.g. in Favourites)

How many searches resulted in viewing resources? I have to verify this
  • 85% of explicit searches and browsing categories
  • 65% of Community browsing (tag cloud and lists)
Millen et al. 2007 speculate that in their study, the a higher click-through rate indicates a more purposeful searching, whereas the community browsing was used more as an exploratrory search activity. I will need to keep my attention on this and whether I can make similar conclusions.

Most likely, anyway, I do not use click-through as an indication of intenet of using a learning resources, what I find most interesting in my study will be how many of the search activities result in a bookmark and/or rating. That is much cooler in my mind than viewing the page. Actually, I've noticed that in our system users view resources a lot, but they do not necessarily show any further interest on them.

That is why I use both implicit and explicit Interest Indicators. By Interest Indicators I mean Explicit Interest Indicators like ratings as a subjective relevance judgment on a given learning content, Marking Interest Indicators like bookmarks and tags on educational content, and Navigational Interest Indicators such as time spent on evaluating the metadata of educational resources, as well as Repetition Interest Indicators as categorised by Claypool, et al., 2001.

In this small study we can see that 19% of viewed resources ended up in users' Favourites. Again, ratings were much less, only about 6% of viewed resources ended up being rated. In the study from IBM system, they had 34-39% as high click-through. Will be keeping my eye on that.

My advisor asked me whether I could find search patterns in my logs. I think I could. In this paper (Millen et al. 2007) they do that :) and here is how: "Looking for Patterns using Cluster Analysis"
To better see the patterns of use, we performed a cluster analysis (K-means) for the different types of search activities. We first normalized the use data for each end-user by computing the percentage of each search type (i.e., community, person, topic, personal, and explicit search). The K- means cluster analysis is then performed, which finds related groups of users with
similar distributions of the five search activities. The resulting cluster solution, shown in Table 4, shows the average percentage of item type for each of four easily interpretable clusters.
Should not be too hard :)

Millen, D., Yang, M., Whittaker, S., Feinberg, J., Social bookmarking and exploratory search (2007). In L. Bannon, I. Wagner, C. Gutwin, R. Harper, and K. Schmidt (eds.).
ECSCW’07: Proceedings of the Tenth European Conference on Computer Supported Cooperative. Work, 24-28 September 2007, Limerick, Ireland

Activity Theory helping us explain folksonomies

I've been lately reading Engeström's (1) stuff and about Activity Theory. In this paper (2) I found a cool reference that explains how using Activity Theory as a theoretical framework we can study learning resource repositories (LOR) and their communities as one single system rather than as a loose set of instruments, subject, objects and outcomes.

I think that is a very important point. I've been arguing for quite a while that tags and social bookmarking can be revolutionary for LOR because now we can make a connection between the user, the resource and its metadata.

Before, it was only the resource and metadata, and a scary looking form for searching the resources (this is time before Google's simple search box, right?). Now, if implemented correctly, social bookmarking and tagging not only helps individuals with their resources management (e.g. Favourites), but also helps other folks to find resources through other users and their digital traces such as tags, number of bookmarks, etc.

To understand Activity Theory it is important to get the bases: everything, well, everything within human activity, is based on the three dominant aspects which are production, distribution and exchange (or communication).
The model suggest the possibility of analyzing a multitude of relations within the triangular structure of activity. However, the essential task is always to grasp the systemic whole, not just separate connections. (no page number in my print, just below Figure 2.6).

This is also the base for the analysis in Margaryan & Littlejohn (2008) for the learning resource repositories as instrument, with rules, division of labour, outcomes, etc.

Moreover, Engström emphasises that there is no activity without the component of production.
The specificity of human activity is that it yields more than what goes into the immediate reproduction of the subjects of productions. One part of this "more" is the surplus product that leads to sharing and sociality, discussed by Leakey & Lewin and Ruben above...(found on the next page)

I was thinking of folksonomies and how the production of tags is first of all good for me. People often times tag and bookmark to "keep found things found", it's part of personal knowledge management activity. Similarly like above, when referred to, for example, production of food that leads to sharing and sociality, in tags, the fact that they are made available to all, leads to sharing and sociality.

I thought that was pretty neat.

Ideas for the design of the "Evidence" study on cross-border use of learning resources

"Psychological tools" helping us explain "Travel well" resources

In the chapter 2, in the subsection called The Third Lineage: From Vygotsky to Leont'ev Engström (1) talks how Vygotsky distinguished between two interrelated types of mediating instruments in human activity: tools and signs. The latter belonged to the broader category of "psychological tools".

Psychological tools
..are directed towards the mastery or control of behavioral processes - someone else's or one's own - just as technical means are directed towards the control of processes of nature. (I guess this is from the same source as the quote above this, this is Vygotsky 1978, 55)
Examples of psychological tools:
various systems for counting; mnemonic techniques; algebraic symbol systems; works of art; writing; schemes, diagrams, maps, and technical drawings; all sorts of conventional signs, and so on. (Vygotsky, 1982:137, cited in Cole & Wertsch)
...and folksonomies :)

I was thinking that the concept of psychological tools is a pretty cool way to start looking into the cross-border use of digital learning resources. My definition is: By cross-border use of digital resources we mean that the user comes from a different country than the resource (cross-country) and/or the resource is in a different language than that of the user’s mother tongue (cross-language).

Many people are baffled about the cross-border use, they always ask me "..but how would teachers be able to make any use of a resource that is in a language that they don't understand".

Let me first elaborate on different types of use of cross-border resources, and then I give my theory on it. The plan is to make a study to see whether this holds or not.

We had a workshop with 35 teachers in science and language learning from different European countries. We asked them to bring along a learning resource that they though would be useful for other teachers in other countries. The observations were the following:

1. Resources that contain psychological tools: examples of this type of resources were in science, biology and math. Here are some examples of the characteristics of these resources
  • How chromosomes define characteristics (e.g. eye color, color of rabbit) or how the human heart works (we actually had examples of this in 2 different languages!).
    If you know the concept (as this would be part of the acquired knowledge of a teacher) you can explain it using this type of examples. It's not important that the manipulations are not in their own language, as the user interface is pretty symbolic and self-explanatory. Also, the little texts in other language did not seem to bother teachers.

  • DNA and how it works, another one on chemistry. The intersting thing is that the text is in Estonian and the resource was intended for pupils, but the group of teachers agreed that they would find it useful as a tool to demonstrate the concept by themselves (note: different intended user group). They explained that they would manipulate the resource for demonstrational purposes, not let the pupils to use it.

  • GeoGebra was one of the examples of a math application. They all loved it! Most importantly, it can be translated easily and it has user communities in different languages.
    Besides those points, they said that as math symbols are commonly shared, it is easy even in other languages. Even this type of applet would be useful for a non-Spanish speaker. BTW, they hated when some resources did not use the proper symbols, but wrote out "tiempo"
2. Resources with more text in a foreign language. One could also observe that some teachers were not minding too much about the text in foreign languages, but they used their pedagogical skills to work that into a challenge to learn.
  • One example from another workshop was a history resource about Greco-Persian war. Although this was already harder to navigate in Polish, a Belgian teacher started coming up with ideas where learners have to solve the language as a challenge. An example was given about a "match the words with an image"-type an exercise about the war equipment of a Greek solder.

  • Another innovative usage was this Japanese virtual reality game, where users have to find their way out of the virtual room with a help of a team. This Hungarian teacher had given it as an English exercise for his students to solve as a group and write down the instructions in English. He said that students were completing the exercise on Friday evening working online with their buddies!
3. Resources that are in the languages that the user has competencies in. This is of course the most used case. If you have studies Russian, for example, you can use resources in that language.

4. Language teachers. This is a group a bit apart too. They, of course, find the whole Internet as their resource for learning! But also the language resources that are created, say, in Finland to study Way finding in French, can be useful in any other language teacher somewhere else. Here the important thing is to make the instructions also in the language that is being taught, so that teachers understand (of course best is making interfaces easy enough without any instructions needed)

So, my theory is that the use of cross-border resources plays on a continuum that has two quite distinct extremes: On the one end we have psychological tools (example 1 and 2) and on the other Foreign language as a tool (example 3 and 4).

The acceptance or willingness of using this kind of material is related to the teacher's previous knowledge and understanding on the topic on the one hand, and on the other, it can be the knowledge or previous experience on coping with foreign languages. Additionally, the pedagogical skills set and pedagogical concepts that are preferred by that teacher drive the final decision on using such material.

A study design

In my study of "Finding evidence" I will only focus on the continuum of psychological tools and foreign language skills. I have a huge dataset from at least 3 or 4 different learning resource environments where users (teachers) have bookmarked or made collections of learning resources that exist in multiple languages.

The dataset currently has 440 users who have selected at least one learning resource to bookmark or add into their collection.
  • Calibrate (176 users, number of posts=1742)
  • LeMill (189 users, number of posts 1645, out of which 238 cross-border actions)
  • del.icio.us (16 users, number of posts 1176).
  • MELT
When I look at the titles of these learning resources, there are 3700 of them. 2992 of these resources have been bookmarked only once. The idea is to sort out cross-border resources (using my definition above), and see whether I can classify them on my continuum.

The good thing is that I know the user languages and country of origin in all the cases, the bad this is that I do not know the country of origin or language of all the resources :( That seems like lots of resources starring.


1 Engeström, Y.: Learning by expanding: An activity theoretical approach to developmental research. Helsinki: Orienta-Konsultit Oy (1987) Retrieved August 25, 2008, from http://lchc.ucsd.edu/MCA/Paper/Engestrom/expanding/toc.htm


2 Margaryan, A., & Littlejohn, A.: Repositories and communities at cross-
purposes: Issues in sharing and reuse of digital learning resources. Journal of
Computer Assisted Learning (JCAL), 24(4), 333-347 (2008)

Monday, August 25, 2008

Notes on Margaryan, Littlejohn and Activity Theory as a framework

Margaryan and Littlejohn (2007, 2008) analysed the mismatches in the perception of repository curators and users. One of the issues really hit home for me:

The curators focus on repository centric factors, while users spotlight a wide range of contextual factors.
They explain this as following: Repositories are frequently introduced to users as sandalone tools. Users, however, see them only as one component within an entire activity system. They recommend that curators and users have to think through the ways in which individual components inter-relate.

This is what I actually realised this summer when we were at the summer school with MELT teachers. At the point where our system failed to work, teachers did not loose too much time but started checking their delicious accounts and bookmarking some interesting learning resources there that had been introduced earlier during the day. That moment, somehow, was an awakening moment for me. I realised that what I've been hassling about for so long, our dear repository, the one and only, is not really one and only source of information for them. Just one among many others that we are not even interested about.

Hence the little idea of integrating users delicous tags and bookmarks on the MELT portal. A logical place for them would be at the Favourites' section: here, on the first tap, are my bookmarks from MELT, and over here on the second tap, are my bookmarks from delicious too. Cool,ugh, inter-relating the services that teachers use. Also, since by default all my Favourites in MELT are publicly available to other users, so would my delicious bookmarks be.

The whole idea goes much further to integrating these using APML to create a profiling tag cloud from my tags from both places. The workshop paper is found here, I still need to work on it a bit.

Other interesting things about the papers:

The study was build using the Activity Theory from Engström 1987 as a theoretical framework. It also might be interesting for me, as I am missing one. Margaryan and Littlejohn (2007, 2008) claim that it offers a holistic framework that allows to study LORs and communities as a single system, rather than as a loose set of instruments, subject, objects and outcomes. It provides an analytic lens to understand the complex relationships wihin each system.

Activity Theory as such belongs to the family of socio-cultural approaches to learning (e.g. Vygotsky), situated learning theoris (Lave) and communities of practice approaches to learning (Wenger, there he is again..). The paper explains that the common denominator for socio-cultural theories is the importance of social and cultural contexts in learning.

From that perspective Activity Theory might make a nice match. One thing why I first was skeptical about it was that Margaryan and Littlejohn in (2007) say this theory offers a method of analysing the development of LORs as participatory environment where knowledge is co-constructed rather than "exchanged" or "consumed". I am not sure whether LORs really were developed in thinking of co-construction of knowledge, at least not before we mixed in the social tagging stuff. From that point, then, it becomes interesting, maybe.

In Margaryan and Littlejohn (2008) authors also talk about how social co-creation of knowledge is facilitated through the use of tools, either concepetual or physical. A dialogue can be such a conceptual tool, but so can email or blogs. Also tags, I guess, can subscribe to that.
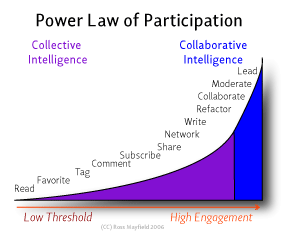
Another thought that came out from reading the 2008 journal paper was that it also talked about Leontiev (1981) and analysing an activity from 3 different levels. The first level related to the overall motive for engaging with an activity. The second level relates to the actions that constitute an activity that are governed by (short-term) goals. The third level of activity related to the operations necessary for carrying out the actions. This made me think of "levels of participation" like in this ladder (or the long tail one). What they also try to depict is that there are different levels of participation, they are differently motivated, and maybe when talking about learning, we can also observe similar levels as pointed out by Leontiev (1981).

A few ideas for the evidence finding paper:
  • The dimensions of repositories and communities can be used to describe the datasets that I will use
Start for the evidence paper: Assume that repositories and learning resources get rid of technical, socio-cultural and pedagogical barriers for usage (references from the JISC report on Learning Communities and Repositories from CD-LOR project), does the re-use across the national and linguistic borders happen? If evidence is found, how much and where?

Engestroem, Y. (1987). Learning by expanding: An activity theoretical approach to developmental rsearch. Helsinki: Orienta-Konsultit Oy. Retrieved August 25, 2008, from
http://lchc.ucsd.edu/MCA/Paper/Engestrom/expanding/toc.htm

Margaryan, A., & Littlejohn, A. (2008). Repositories and communities at cross-purposes: Issues in sharing and reuse of digital learning resources. Journal of Computer Assisted Learning (JCAL), 24(4), 333-347.

Margaryan, A., Littlejohn, A. (2007) Communities at cross-purposes: Contradictions in the views of stakeholders of learning object repository systems. Proceedings ascilite, Singapore 2007.

Sunday, August 24, 2008

How do tags connect to the Thesaurus terms?

Our social tagging system in MELT is special in two ways:
  • one, we support multi-linguality
  • two, we have not only tags, but all resources that users tag also have Thesaurus terms
In that context it becomes very interesting to know how do tags relate to the Thesaurus terms that have been used to index the resources that users tag.

I took a sample of tagged resources (n=185) that have 1013 tags associated with them. Out of those tags, there are 595 distinct tags. There are 44 users.


I made a network diagram visualisation that displays the Thesaurus terms as nodes that are connected by edges to tags. You'll find it here to play around with it. Unfortunately, I found out that 24 resources did not have Thesaurus terms related to them(that's about 13%, hmmm), thus a big plumb node in the middle without a Thesaurus term.

There is another visualisation here, it's more explorative about the data.


It's rather interesting that 595 distinct tags from users can be comprised to 34 thesaurus terms. That is 17,5 tags per Thesaurus term on average. Of course it does not go like that, it's more like rich-get-richer-type of a story. In the visualisation above you can see that most tags are related to language learning, for example.

If you look at the distribution of tags you'll find that many of the top tags are also about languages. Interestingly, many of them repeat the topic of the resource, but some of them (clearly less) state something about the nature of the resource (e.g. interactive) or the type (e.g. exercise).

The problem with creating this kind of visualisation of tags on the system level will be that the resources seem to have too many Thesaurus term. If there are 5 or so indexing terms, everything becomes related to everything else. It might be interesting to either to ask limit the Thesaurus terms to three (as should be the case anyway) or ask the indexer to give one term priority over others.

The same also goes for content-based recommendations, btw. If there are too many terms, you recommend everything for everyone.

Wednesday, August 20, 2008

On the memory lane of the Internet - Paris 8

It's great to be getting older. It turns the Internet into a memory lane, something like cleaning your old cupboards in the place where you grew up, finding old pictures, mails, etc.

I just received a mail from someone asking me if this (updated link to Internet Archive: https://web.archive.org/web/20090501062208/http://membres.lycos.fr/riina/dea.html) was something that I have written. It was "mon memoire du DEA" from 1999 in the department of Hypermedia in Paris 8! I have not even put my name on it, but somehow this person was able to find it and associate it to me. Best of all is that she still found it useful for her studies, she wanted to cite it in her own dissertation on language teaching and new technologies, but since the text did not have the author nor the publication date, she found me. You never know, do you now..

So here it:
Riina Vuorikari
ENSEIGNEMENT ET APPRENTISSAGE
LE CAS DES LANGUES ÉTRANGÈRES
EFFETS DES TECHNOLOGIES DE L’INFORMATION ET DE LA COMMUNICATION
Date de parution: septembre 1999
Lieu de publication: L'Universite de Paris 8, Saint-Denis, France.

Notice the way that the title was written, no commas but different lines. Pretty arty, ha? It was mostly influenced by, hm, my really eccentric pormotor, J.Feat. So, I went back to my Yahoo! mail that I used already back then to check the mails between us when studying. Man, he was somewhat strange, but who would not be in Paris 8!

I always joked that the hardest task in it all was to get out of there with a diploma, what a mess. But Fun. A good place to hang out. Check out what the French version of wikipedia says about it. The English version is lame, it's hard to capture that feeling of "papa cools", all the old hippies from the late sixties who had installed themselves there ever since the Youth revolution of 1968. Every day there was (I bet still is) a student "manif", a little protest or signing a petition on this or that. When I read parts of my dissertation I noticed how that radicalism had snuck in..

D’un côté Internet offre " un accès libre au monde ", il est " international, pluriculturel et multilingue ", mais ceci est une image idéalisée d’Internet. D’un autre côté Internet est vu comme un média conditionné par McWorldet par les concepts d’américanisme à l’échelle mondiale. L’homogénéisation culturelle et le commerce électronique comptent sur l’idée que la consommation devient l’unique activité humaine qui uniforme le goût des consommateurs.

..and at the end about the future perspectives:

Une autre piste de recherche sera l’industrialisation de l’enseignement. Les questions soulevées par ces tendances sont multidimensionnelles : Est-ce que l’interaction humaine pourra être remplacée ? Est-ce que les enseignants qualifiés seront remplacés par les moins qualifiés une fois que le contenu du cours est mis en place sur Internet ou sur le cédérom ? Qui aura la propriété des contenus de ces cours qui sont devenus des produits à exploiter, le professeur ou l’administration de la faculté ? Qui aura l’intérêt à vendre ces contenus, qui aura les droits d’auteur et qui va gagner l’argent ?
Outch. Then again, there is lots of good stuff too. I love the translation of knowledge network in to "le tissu de savoir" or calling the whole Internet as " tissu social virtuel"! What a foresight! I remember sitting with my supervisor in the Montmartre graveyard and he was explaining that instead of talking about the Internet, I could use the term " tissu social virtuel", like a web woven in a tissue where the threads are all intervened, to illustrate the use of the Internet. pretty funny in its own way..

This is my opening line:
Internet est souvent associé au concept d’interactivité. Est-il possible d’exploiter cette propriété pour mettre en œuvre des techniques spécifiques pour l’enseignement de langues vivantes étrangères ? Au contraire de l’enfant qui apprend sa langue maternelle dans un environnement naturellement interactif - et de façon permanente - l’étudiant suit régulièrement un cours où l’immersion linguistique est artificielle et de courte durée. Jusqu’à quel point est-il possible de reconstituer, à partir d’un tissu social virtuel (=Internet) les conditions idéales d’apprentissage, particulièrement l’apprentissage des langues étrangères ?
I remember when I finally was writing my dissertation, my promotor was merciless. He really cracked the whip on me. But he knew how far to push, and at the end also I was really pleased with the result. After all, it was mention bien. When I thanked him for this, he said " Please, don't you give no "thank you" -- after all, it's my job...". That's a true educator! But hey, he could have taken some credit for it.

A funny thing was that he's English was perfect, but I only learned about that after we were done with all the writing. He was harsh on my French too. When I had already handed in the first version of my dissertation, he congratulated me on it. But half way down on his mail he says that in its current version no one can read it without lots of difficulties :
Toutefois, tu ne recevras ton diplôme que si tu déposes plus tard un nouvel exemplaire, corrigé de toutes les fautes de français -- il faut comprendre que cet exemplaire est destiné à la bibliothèque, et que, tel qu'il est, personne ne peux le lire sans une grande fatigue...
The final discussions that we had before my defense took place in Montmartre. We once met in that same café where they shot scenes for Amelie, or at the graveyard. I was quite surprised to see them in the movie, I remember.

It was also fun now to check out on some professors from Paris 8. I found Jean-Pierre Balpe who at the time was the head of the department of Hypermedia. Jean Clement who taught us a course on hypermedia. Imad Saleh, one of my "rapporteurs", is now the head of Laboratoire Paragraphe, that's the nickname of the deparment (so French, I love it!). Or Jean-Lois Weissberg - I never understood anything about his lectures, he talked about "telepercence" and such. I only remember that soulful intellectual Greek philosophy student who engaged in discussions with him about things that I could not follow. After all, they all carried the legacy of Pierre Levy who had just left the department year earlier.

I tried to dig out on my Lycos account where this stuff now resides, but I could not find my password and the system does not recognise my username :( But I found some other old stuff, like the index page of the site that I made at that time for Finnish students in Paris, Suomalainen Osakunta, my cool looking CV and the side of akseli that Pia, "Puumatyttö", teki suomalaisille taiteilijoille ja jota autoin jossain vaiheessa. Ihanaa!


Well there, that was a nice moment of memories from Paris and end of the Millennium.

Thursday, August 07, 2008

Can Social Information save teachers' time when choosing interesting learning resources?

One of my research questions is aimed at understanding what so called Social Information can do to help teachers to choose the right learning resources from a seemingly overwhelming collection. By Social Information I mean information about previous users' interactions with the resource. I am mainly interested in explicit annotations like ratings and tags, and more implicit ones like bookmarks.

As I'm interested in the use of resources that come from different countries than users do, I think Social Information (SI) should display not only annotations, but also information from where the user comes from.

One thing that I hypothesise is that among other things, Social Information, when associated with conventional metadata about learning resources, can make the decision making process faster for teachers when, for example, looking at the search result list. As a multilingual context in a repository can result in metadata that is in different languages, it could be speculated that Social Information indicating the origin of the users who have previously annotated the resource, could help the other users to make up their mind (see the image for an example).

We were interested in two different aspects:
  1. Does the appearance of Social Information make the decision making process any faster?
  2. Does the appearance of Social Information make the users choose more resources?

Method

We had 25 users from five different European countries. These teachers are primary and secondary teachers in science, language learning and ICTs in Finland, Estonia, Hungary, Belgium and Italy. xx of them are females and xxmales. xx participant is under 30 years old, xx are under 40 years, xx under 50 years, xx under 60 years old.

They have been part of the MELT project since Summer 2007. In March 2008 they were invited to create a profile on the MELT portal, where they are able to access multilingual learning resources for different topical areas.

We designed an experiment where teachers were shown two different imitations of search results list with learning resources and their associated metadata. One of the lists showed what we call the conventional metadata, such as title, url, language of the resource, a short description, subject area, type of content and its target audience. Here is an example.

The other list had the same metadata, but we also added the Social Information from the previous users. This could be the tags in their original language, the number of times bookmarked (favourites) and the ratings. Also, for bookmarks we would mention from which country the users come from. As example of this was shown above, the first image in this post.

We had 48 learning resources that came from different countries and were in different languages. About half of them were in English and other half in other languages, this also seems to reflect the division of the resources that users have bookmarked on the portal. The resources were about language learning, primary education, ICTs and science material, those were the areas of the teachers. I'll prepare better information about this later.

We had 12 learning resources on a page imitating a list of search results that user could get on a repository. In total, there were 4 such pages for each user, we call them sets. Every second set had conventional matadata, and every other had additionally also Social Information as indicated above.

At the beginning of the each set the participants were asked to write their names and the time when they started with the set of 12 resources. At the end, when they submitted their results, the system recorded a time. To answer to our first question we were interested in how much time do teachers spent to evaluate the appropriateness of 12 resources for them.

The teachers were asked to look at the metadata of the resource and the resource itself if interesting, and were asked one single question: "Would you use this resources, or parts of it, in your teaching in next Fall?" They answered on a scale 1 to 5, 1 being "I don't teach the topic", 2= No, 3= Maybe not, 4= Maybe and 5= Yes. Looking at the number of resources that users choose in their topical areas would give us indication of whether resources that have more Social Information related to them were more often chosen than the onces without.

Because of the low number of participants (n=25) we decided upon a within-subject design for this experiment. This is the one where the same group of subjects served in both treatments, i.e. they received both the material with conventional metadata and with social information.

Moreover, we had the participants in two different "groups". Group 1 had 12 participants and Group 2 had 13. Group 1 started first with a set with conventional metadata and Group2 with a set of resources that had Social Information added to it. When analysing the results, we found that one user in Group 2 had consistently added incorrect times. We excluded these times from the counts for time spent per set, leaving 12 participants in each. Moreover, in both set there were a few cases where the start time was forgotten.

Results

Descriptive statistics

We had 1129 responses to our questions, which means 71 responses were left blank. In 53% of the cases the users had answered that they do not teach the topic, which means that they deemed the resources not suitable for the topical area that they were teaching. 25.6% of the users found resources that they said that they would use (yes or maybe yes), whereas 21.6% of the resources were not found of use in the upcoming school year (not, maybe not). The mean for the responses was 2.23 (Min=1, Max=4), standard deviation was 1.138.

Q1: Does the appearance of Social Information make the decision making process any faster? Time spent on 12 resources (i.e. set)

On the average, users spent a bit more time on the sets that did not contain Social Information. The average to review a set of 12 resources with conventional metadata was 9 minutes and 8 minutes with Social Information.

I do not know yet whether this is a significant difference (my SPSS license ran out), but one could assume it is at least a sign of good news for Social Information. We can imagine that users go through a lot of resources when browsing a learning resources repository (I currently do not have the logs about the number of resources that users review per session, but I will produce them). So if you think of small cycles and multiply that number with, say 1o times, you could come up to some significant time savings when Social Information is made available to speed the decision making process.

Individual differences

Still looking at the average times spent, we can see that there were many individual differences. In the chart below the blue lines show the amount of time that participants spent with conventional metadata and the red one with Social Information added to it. You can see that for some users one metadata setting seems like a faster way, but anyhow, the lines follow one another pretty closely, apart from some odd-balls (like user 23). You can also see that there seem to be a wide variety of personal ways, some users scrutinise resources with a great care (user 7 and 8), whereas some go through them very fast (user 16 and 17).

I'd like to mention that here it does not matter that some of the resources are not in the competence area of the participants. We focus purely on the time that they spent going through pages and making decisions whether some of the resources are useful for them in the upcoming school year or not. However, this becomes crucial to answer to our second question:

Q2: Does the appearance of Social Information make the users choose more resources?

Table below presents the results when I looked at the amount of resources chosen per set. There was 4 different sets and each contained 12 learning resources in different languages. The two different treatments meant that teachers reviewed 2 sets with Social Information available, and two sets without. As teachers were from different tpical backgrounds, I excluded the responses from users who said that they do not teach the topic of the given resource. In table below you can see the percentile of positive responses (maybe use, use).

It appears that consistently teachers chose more resources when the Social Information was not available. This is contrary to what I expected. I have not calculated the significance of these results, but the differences do look big. In some cases, like in the 2nd set, even about 15% in favour of no Social Information available.

In a way, maybe the appearance of SI makes the teachers more careful or critical to choose the resources?

What is needed now is a follow up study at the end of this school term to check whether these teachers actually used the resources in their teaching. Or, I could check if they have bookmarked these resources on the MELT portal. They know the resources are available there. MORE to follow...