Friday, February 27, 2009

Are tags from Mars and descriptors from Venus?

A study on the ecology of educational resource metadata.

I just finished a paper on the tag evaluations that we did in the MELT project. We had lots of fun with the name of the paper :) the main question being which one, tags or descriptors, should be from Venus...?

Anyway, we were able to show that not all the tags are as far from the Thesaurus descriptors as Mars is from Venus. We had different perspectives for evaluations: end-users, expert indexers and repository owners. For me the most interesting thing that came up was that 11% of end-user generated tags are actually terms that we can find in our multilingual Thesaurus! I assume teachers are "better taggers" than average, usually there is lots of talk about the gap between end-users' language and the one deployed by experts.

Abstract. pdf. In this study, over a period of six months, we gathered empirical data from more than 200 users on a learning resource portal with a social bookmarking and tagging feature. Our aim was to look at the tags from different stakeholders’ points of view; end-users, librarians/expert indexers and repository owners. We first look how users tag resources, and then conduct an evaluation with indexers to understand how they perceive the value of tags as descriptors. We then present a case study from a repository owner’s point of view. Lastly, we study users’ clickstream when searching resources. We find that, even though end-users and expert evaluators apply very different strategies when adding metadata, (end-users have a rather synthetic approach whereas expert indexers an analytical one) there is an overlap in the information in tags and the official descriptors, this overlap is even up to 51%, creating an ecology of metadata.

Keywords: Learning resource metadata, tags, folksonomy, clickstream,
thesaurus, evaluation.


Monday, February 09, 2009

"Thesaurus-tags"

One of the particularities of the MELT portal is that apart from being a "traditional" resource portal, we also have social tagging-features implemented. This creates a situation where resources have both indexing terms that come from our multilingual Thesaurus, as well as teacher generated tags, that, btw, are also multilingual.

I was looking at the tags today with a specific question in mind: "How many of the user-generated tags are actually terms that exist in the Thesaurus?" If there is a tag that is added by a teacher, and if it exists in the Thesaurus, I will call it a "Thesaurus-tag".

Here are the figures:
  • Distinct tags: 4428
  • Tags applied: 5009
  • Distinct "Thesaurus-tags": 505
  • "Thesaurus-tags" applied: 714
I was actually really impressed: 11.4% of distinct tags are "Thesaurus-tags"! And if we look at tag application, "Thesaurus-tags" amount to 14.25% of all tags.

Moreover, 22.37% of distinct "Thesaurus-tags" are applied more than once. This amounts to 45.1% of all "Thesaurus-tag" applications! The top "Thesaurus-tag" were:
Europe (10), music (8), test (8), Vocabulary (8), Internet (7), art (6), biology (6), history (6), Australia (5), chemistry (5).

This is really quite interesting. On the one hand, we always ask ourselves how to make the Learning resource indexing better, and here we can totally "crowd source" part of the indexing, that is usually done by the experts", to end-users. If we think an end-user thought that a Thesaurus-tag was good enough to add for a resource, I can be pretty sure that it is also good enough for being an indexing term. The story can be VERY different for all tags, we do not think that ALL tags could become indexing terms, although we know they are good for other stuff.

On the other hand, being in the multi-lingual context, we have always a bit hard time with tags in different languages. At least with "Thesaurus-tags" we could easily show a translation of the tag, as we are certain it to be a good one.

There are lots of interesting things to see, for example, whether these resources previously had the same indexing term as the "Thesaurus-tag" was, i.e. was the tag redundant or does it really add some value to our system. It will also be interesting to see whether there was a trend; the resources that had poor/little indexing terms received more "Thesaurus-tags" from the end-users. Well, lots more, I guess, but that will be for another time.

Tuesday, January 13, 2009

Modelling the portal ecology: What goes around comes around

The three main actions on the portal: discover resources, play them and annotate. The two main group of users: ones logged-in and the others not.

I've divided the resource discovery process in three slots (Millen et al.):
  1. Explicit search
  2. Community search
  3. Personal search
Play is when the user clicks on the link. We also call this implicit interest indicator, however, we are not sure whether it was relevant to the user or not. Worth noting anyway. This is also called "hits" or "click-through" in some lingo.

Annotation is when the user makes an explicit interest marking (indicator) on the resource, this can currently be either a rating (usefulness, scale 1 to 5) and bookmark with tags. Both of these actions are public.

About users and logs

In general terms we record all kinds of clicks and actions on the portal (see here). I studied the logs from the last 2,5 months. We know that we have 340 users who have a user name, excluding staff, etc., we have 168 "real" users. Out of them 82 had clicked on a resource on the portal at least once, so these users are included in the logs. Additionally, there are users who do not log, but I do not have any idea currently how many they are (check Analytics). There were 13 604 actions recorded, 40% from the ones who logged in and 60% by others who did not log in.

In general, we can think that the relationship between these 3 actions is important on the portal and can indicate something about its efficiency for users to get what they want, as well as for the system to get what is needed to keep it going. In our case, we are in the process of looking at how Social information can help the discovery. So, a perquisite is to have SI available, thus the system needs ratings and bookmarks.

With the contributing users (=logged-in) on the MELT portal:
  • 2 searches result to one play;
  • 2.6 searches result to one annotation, this can be either rating or bookmarking;
  • 1.3 plays result to one annotation.

For the comparison, in Calibrate the figures were the following:
  • 0.5 searches result to one play;
  • 5.7 searches result to one annotation, this can be either rating or bookmarking;
  • 11.3 plays result to one annotation.
I will study this further too. A quick look would say that a system, which emphasises Social Information for users own benefits (Favourites) and for everyone's benefits (allows Community browsing) like is the case with MELT, the loop for getting annotations is more efficient than in the system which does not make use of such information (e.g. Calibrate). The ration of search-to-annotation is 2.6 to 1 in MELT, whereas the same in Calibrate is 5.7 to 1.

However, if we look at the ration of "hits", the Calibrate system has been four times more efficient: it took one search to play 2 resources, whereas in MELT it took 2 searches for one play. The MELT system search function has been under constant development for speed, which has been somewhat problematic due to huge amount of content. I will report later on the same ration after our last optimisation effort.

What goes around comes around

Graph 1 depicts what is going on on the portal. I will explain this later in details. For each action I have indicated the percentage of total, e.g. Explicit search 78% is from all Explicit searches executed by non-logged in users.


Graph 1


Monday, January 12, 2009

Discovering cross-boundary resources on the portal

This is continuation for the previous post, the same data-

The question now is how and where do users discover cross-border resources? By this I mean that the user and the content come from different countries, and/or that the content is in a language other than the user’s mother tongue.

One challenge is discovering resources in general (previous post), another one is to discover resources that are in a different language and come from different countries. This is the case on our portal, so I'm interested in how to facilitate the discovery process that involves crossing those boundaries (language and national, which might have implications to the educational content of the resource), and hopefully make it more efficient.

My take is social information: making it readily available to all to leave cues from other users. I bet that this should facilitate the discovery process and thus also make it more efficient (more resources and faster).

So I looked at the previous data and the cross-boundary bookmarks from users. This is relative to the user, of course, so with every bookmark I compare whether the resource and the user come from the same country and/or is the users mother tongue different from the resource language.

41 out of 48 active users had bookmarked cross-boundary resources. They had added
  • 299 distinct resources into their collections 350 times. Out of these resources
  • 163 were cross-boundary resources, which had been added to their collections 198 times.
  • This means that 55% of distinct resources obtained during the period of 1.5 months were cross-boundary resources.
So it was interesting to see how many of these resources had Social information added to them?

Table 1


Table 1 shows that about a third of the bookmarked cross-boundary resources had Social Information on them, they were either bookmarked by previous users or existed in the "travel well" list. This is cool! Although we cannot say that the users only discovered these resources because of Social Information, it is important to know that it has had added value for users to discover them. I also found out that about 10% of bookmarks on resources with SI had been previously bookmarked by someone from the same country as the resource was. The fact that they were bookmarked, although still almost dismissible small (10%), is still good news for SI and social navigation based on it.

I then looked at where the resources are discovered: 62% of cross-boundary discoveries were done in Search Result List (SRL) whereas 37% took place in Community searches, most of them in the tag cloud (30%) and 7.5% on the Travel well and Most bookmarked lists (only one case in the latter :(

As comparison for the resource discoveries that did not cross any borders (e.g. German teacher found German resources), 90% of them took place in SRL. So it seems that for discovering cross-boundary resources the Social Information is important, as it allows users to do Community searches to discover these resources. We do see, though, that cross-boundary discovery is efficient also within the resources that cannot leverage the previous user experiences, as 63% of cross-boundary resources do not have any SI.

Interestingly, when we look at Table 1, we see that for the resource discovery that does not imply any cross-border action, users do not seem to care much for SI. Actually, more than 90% of these bookmarked resources had no SI. This is cool, as it seems that we need users to discover and annotate resources among their comfort zone (e.g. national and regional educational material in their own language) in order to make it more readily available to others.

Another thing that I've looked at are these measures for
  • usage coverage within the repository,
  • how many resources are shared among collections (e.g. Favourites) and
  • what I call the pick-up rate, this is how many of distinct used resources are reused. This could happen when someone discovers a resource that has SI related to it (e.g. in the travel well list or from other user's favourites, or just picks it up from SRL based on someone else's annotations). These were discussed in more details in the last paper.
Table 2


Table 2 shows these measure in LeMill, Calibrate and delicious, additionally, the gray column indicates this 1.5 month trial in MELT and the last column has all the data from MELT, which includes the pilot teachers, staff, partners, etc.

We can see that as the initial amount of resources is so big in MELT, we still cover only a minimal amount of resources, from 1 to 2 %. This does not even include the assets, which more than doubles the amount. Used here means that the resource is added to Favourites once (reuse more than once).

We can see, though, that even if the resources coverage is not that high, there is still quite a lot of sharing among used resources. This figure still remains low with 1.5month trial (about 15%, same as in Calibrate which did not make the SI available!), but if we look at all the usage so far, the sharing is at 43%. This is somewhat artificial, though, as there is a lot of staff use, but still I hope it indicates that making SI available on the long run helps sharing resources (or, I need to look better solutions on the portal for sharing, which is also planned but super delayed because of all the other dev programme).

We can already see that the pick-up rate is higher in MELT trail than in the 3 other platforms that I've looked previously. This is an indication that SI works, I hope.

Btw, I could not find any correlation between the act of putting the resources in Favourites and whether they have Social information related to them (I got some lousy 0.18 even if I removed 2 outliers who outperformed anyone else). Also, in some previous test I had hard time finding significant changes, so I might need to seddle with increased reuse rate, which has previously been shown to be abotu 20% across collections. I found that it was about half of this (or the same as general reuse) in my previous paper.

Saturday, January 10, 2009

Where does a CC-licence take you?

..or better, your photos? Some time ago one of my pics was "selected" for a travel guide from Prague. That was pretty cool and I really appreciated it. Tonight, I was checking my Flickr stats and noticed that one photo had been viewed many times recently. So I looked what's up with that.


I followed the referrals. Here are the top 3 sources, some other hits were through search engines for generic keywords like ski, etc.

1. It was the main picture on the Facebook group for Sankt-Anton fans.


2. It was on a Yahoo! travel website for best skiing in America. They had a Flickr badge with some random ski shots, et voila moi! (see the small image on the right corner)


3. The funniest of all, though, is that it is one some German photo website where the dude discussed how the picture should have been framed differently! Hmm..I think my boyfriend, who took the picture, did not appreciate this lesson..


It's just kinda weird to find yourself in odd places on the web, but hey, isn't that what the creative commons license is supposed to allow. So this is just one consequence of it, I guess.

Talking about odd places to be on the Web, the other night my Google alerts had picked up that my blog post appeared on a porno site. Sure enough, there after lots of photos of youknowwhat, were feeds from my latest blog post. Pretty hilarious... I don't recommend clicking on the link, but you can read the paper though!

Wednesday, January 07, 2009

Out Now: Special Issue on Social Information Retrieval for Technology Enhanced Learning

I am glad to announce the Special Issue on Social Information Retrieval for Technology Enhanced Learning (SIRTEL) which just came out today in Journal of Digital Information (JoDI) Vol 10, No 2 (2009)!

I co-editored it with Erik Duval and Nikos Manouselis. The following stuff's in it, enjoy!

Special Issue on Social Information Retrieval for Technology Enhanced Learning HTML
Erik Duval, Riina Vuorikari, Nikos Manouselis

Articles

Identifying the Goal, User model and Conditions of Recommender Systems for Formal and Informal Learning Abstract PDF
Hendrik Drachsler, Hans G. K. Hummel, Rob Koper
The Pedagogical Value of Papers: a Collaborative-Filtering based Paper Recommender Abstract PDF
Tiffany Y Tang, Gordon McCalla
Lost in social space: Information retrieval issues in Web 1.5 Abstract HTML
Jon Dron, Terry Anderson
Exploratory Analysis of the Main Characteristics of Tags and Tagging of Educational Resources in a Multi-lingual Context Abstract HTML
Riina Vuorikari, Xavier Ochoa
Visualising Social Bookmarks Abstract PDF
Joris Klerkx, Erik Duval


A Special thank to people who participated in the PC:
  • Alexander Felfernig, University of Klagenfurt, Germany
  • Brandon Muramatsu, Utah State University, USA
  • David Massar, European Schoolnet, Be
  • Hendrik Drachsler, Open University of the Netherlands, The Netherlands
  • Jon Dron, Athabasca University, Canada
  • Marc Spaniol, Max-Planck-Institute for Informatics, Germany
  • Martin Wolpers, Fraunhofer, Germany
  • Miguel-Angel Sicilia, University of Alcala, Spain
  • Nikos Manouselis, Greek Research & Technology Network, Greece
  • Rick D. Hangartner, MyStrands, USA
  • Salvador Sanchez, University of Alcala, Spain
  • Xavier Ochoa, Escuela Superior Politécnica del Litoral, Ecuador
  • Yiwei Cao, RWTH Aachen University, Germany

Tuesday, January 06, 2009

Users on the portal: consuming and contributing

I continued the previous study with more data: this time I took all the logs from Oct 1 to December 18 2008. The idea, again, was to see how much the previous annotations (ratings and bookmarks) would "guide" the choice of new users.

The datasets:

1. All bookmarks and ratings in MELT until Oct 1 2008. This comprises of 565 distinct resources. We call these resources with Social Information (SI), as it is something that is shared and made public by users.
  • 88 of these resources were on the list called "Travel well" resources. They are made available directly from the portal front page. They were recorded to the system by a user called "EUNRecommender" suggesting that these resources should be of interest and good quality. Additionally, annotations from other users were made available.

  • 477 of these resources were annotated (ratings and bookmarks) by previous users. These were either the pilot teachers, project partners and staff in the office. The top bookmarked and rated once would appear on the "Most bookmarked list", also accessible from the front page. Similarly, annotations from other users were made available.
2. I took server-side logs from the period of Oct 1 to Dec 18 2008. At the end of this period the portal had 340 users registered, out of which some people never used the portal when logged in and a number was project related staff. We excluded those people from the logs and were left with 168 users, out of which 82 had clicked on a resource on the portal at least once. Additionally, users who do not log in are recorded, so our click-though includes many more users. This group had:
  • clicked ("played") on 1711 distinct resources (all users);
  • out of which 974 were clicked ("played") by logged-in users (82);
  • bookmarked 294 distinct resources 351 times;
  • rated 323 distinct resources 385 times;
    = 394 distinct resources annotated.
The method for this study is a manual log-file analyses using my own defined logging scheme (see here).

Questions: How and where on the portal do users discover resources, do they rather discover new resources or re-discover once that have been annotated by others? Are the suggestion lists like "Travel well" resources or "Most boomarked" effective, i.e. are many resources discovered through them?

We split our understanding of "discover resources" meaning two different things and look at the separately. Discover meaning:
  1. finding the resource on the portal, clicking on it (i.e. play). This is also called implicit interest indicator;
  2. finding a resource and creating an explicit marker on the resource in terms of rating or bookmarking with tags (explicit interest indicator).
The first one is important to know how big coverage the resources that have been "touched upon" or "hit" cover from all resources in the repository (use). The second one, is important as it creates explicit maker which can be used for cues and social navigation purposes. Moreover, the second one can be used as a proxy for reuse. For reuse we use the following definition: " resource is integrated in a new context with other components, and when this occurred more than once, we consider the resource reused".


1. Who discovers resources?

Out of 82 active users, 63 had annotated a resource at least once, 75% had annotated more than once. Average was 11.6 annotations, median 4. The top two users annotated 120 and 108 times, the following users 50 times. There were 36 users who bookmarked and rated, and 14 users who only bookmarked and 13 who only rated.


2. What kind of "actions" take place?

By actions, in this case, I mean playing the resource (click on the link), bookmarking and/or rating it, but also viewing evaluations related to this resource or checking the "Favourites" from the user who had discovered an interesting resource.

Table 2 presents data on how the users (described in 2. above) interacted with resources. The left column explains where on the portal this action took place, whereas the top row indicates the action. There were total of 3542 actions related to this.

In general, this group annotated 75% resources in SRL, 15% in tag cloud, 4% on the Travel well list, 3% in their own favourites (ratings) and only 1% on Most bookmarked list.

Table 2


Let's first look at what happens in the Search Result List (SRL). Table 2 shows that most things happen when users are here: resources are played more than 2000 times (2/3 of all plays), most rating (70%) and bookmarking (73%) of "virgin" resources also take place here. We can also see that some small amount of resources with SI are rated and bookmarked from SRL (less than 10%). This indicates that some users paid attention to cues made available by previous SI and found them useful.

Mostly, though, it's "virgin" resources. This is a good news, in a way, as I was worried that users might be lazy and not discover resources that other users have not annotated before. On the other hand, most users click on resources and never annotate them, so we are left to guess whether they liked them or not... only 13% of these clicks lead to rating the resource (268), for example.On the average, 71% of virgin resources "hit" get annotated, and 29% of resources with SI get annotated.

Table 2 also shows that the tag cloud is a good catcher of ratings (15%) and taggings (15%), whereas the "Travel well" list is a real hit catcher. 13% of hits on resources with SI are played here. This list was comprised of 88 resources, out of which only 54 got played. The average was 6.8 plays/resource (median 3.5), but in reality, some got played a lot more than others. 30% received more than average hits. The highest were 30, 29 and 28 (great, just checked the top dog, and it's a dead link :(.

The story looks worse for actually bookmarking and rating resources from the Travel well list, only 18 of them got hitched (20%). 2 got bookmarked twise and two rated 5 times (no overlap). So, I suspect that we did not succeed that well in creating appealing "recommendations". I'll get back to that point at a later stage. A rather effective features of TW list was the use of "view evaluations" and "view other users", about 40% of both were generated here, so they helped users to social navigate the portal.

Compared to "Travel well" list, the "Most bookmarked" resources did not seem to have the same effect of chatching eyeballs. This is bizarre, as both these are available on the font page, however, "Most bookmarked" are a click away on the tab. As 84% of these hits come from users who are not logged in, I think it might be lots of clicks from our testing period, but also it's possible that this is only what users experience on the portal and then fly away (forever..?).

Lastly, table 2 shows that some ratings take place in Favourites. That's good, since we intended favourites to be the place for that. I imagined that teachers first want to use the resource, so they put it on thier favourites and then come back later to rate it. Well, users know better, they seem to take about a second to view the resource and bookmark it on the SRL. I will have to look if there is any qualitative difference between ratings of the ones in SRL and Favourites?

3. Where do these actions take place?

I was also interested in seeing what kind of search methods do users choose to use. Possibilities offered on the portal are the following:
  • Explicit search: using traditional search box with text or advanced search options. This results in resources on a Search Result List (SRL) where users can view the metadata about the resources as well as the annotations by others. Searches within results in SRL can also be refined, or ranked either by popularity or ratings. Also "Browse by category" results in this.

  • Community browsing: These include browsing the tag cloud, and examining bookmarks created by the community. In our case these are lists of most boomarked items; travel well; tags; other people Favourites.

  • Personal search: Looking for bookmarks from one's own personal collecction of bookmarks (Favourites)
Table 3.


Of all searches 76% were Explicit searches, where 21% Community searches and 2% personal searches.

What comes to spearing actions on other things on the portal, we can observe some differences between the logged-in and not logged-in users. Whereas not logged-in users spend most of their actions on searching (60% + 17%) and playing resources (23%), the logged in users have a more variety.

The logged-in users search differently, they use far less the Explicit search function (28%) and also spend less time on the Community search (only 8%), but additionally they have the Personal search function available (3,5%). The difference here is that these users can interact with the resources that they have found earlier ("keep found things found"). There is quite a huge difference between how much actions are spent on searching between these groups, 77% vs. 40%. Logged-in users also play less resources (18%), but still "outsmart" not logged-in users in terms of searches returning plays:
  • the first group spears 3.4 searches to play one resource, whereas
  • the logged-in users spear 1,98 searches to play one resource.
This apparent inefficiency is partly due to the fact that we are still testing the server and probably many tests are done when the user is not logged in. However, this is something to remark for now and keep the eye on (check: can I omit the searches from the office using the data from Analytics).

A major difference between the two groups is what I call contributing actions. We already have seen that 27% on resource with SI get played and that on the average 13.3% of searches take advantage of Community browsing. We also saw that some 6% of annotations on the SRL are on resources that have Social Information related to them. So where does this social information come from?

In Table 3 we see that contributing actions cover about 40% of all the actions by logged in users. This is about 16% of all actions during this period! I will come back to this point later trying to make a picture of what the input is by a group of logged-in users and how it can be taken advantage of by other users of the system.

4. What resources do get played?


Users can access 30116 learning resources through the portal, and many more assets. During the trial period, 1547 distinct resources got played 2828 times by all users. That make an average of 1.83 plays/resources, but in reality some get a few hits and a few gets many hits (median: 1). 27% get more than one hit, most hits were 35 ( strangely, this resource was not even bookmarked "123216875").

I was interested in what happened with resources that had Social Information vs. the ones that were "virgins", not yet annotated by previous users.

Of the total plays (2828 times) 73% were on resources without SI and 27% on resource with SI. If we look at it from all resources that were made available, out of 565 resources with SI 34,7% were played at least ones, whereas from all other resources (29551), 4.57% got played at least once. Also, some of the newly annotated resources got hits right away, we have 54 resources that got played 70 times, most likely thanks to their new annotations. Some of these newly annotated resources (32 cases) prompted 99 further annotations from the new users. These 99 annotations were made both in SRL (69%) and in social navigation areas like tagcloud and Favourites (31%). This shows that these new annotations became useful to other users right away, actually more so than the previsouly annotated resources, out of which only less than 10% were found of use by these users (31% vs. 10%, see Table 4).

It's quite interesting, though, that only about one third of resources with SI got played. I would have thought that it is more. This might be due that our search result list is not ranked to start with. It is possible for the user to re-organise the results by popularity or ratings, but actually we do not know whether this happens (currently have not found a way to log it). I guess the other side of the coin that surprises me is that users clicked on so many resources that did not have any annotations on them. I guess it's a good sign of curiosity :)

Interestingly, we find that users who are logged-in discovered less resources than the others. Out of all these resources (n=1547), 68% were played by users who were not logged in and 44% by logged-in users (last row in Table 1). The same can be observed for resources with SI and not.

Table 1.


5. How many annotations per resource?

Of the total amount of annotations received during this period, we can count that 394 distinct resources received 734 annotations, they were half and half ratings and bookmarkings.
  • 322 resources received 383 ratings. 13% received more than one rating, average 1.18. Top amont of ratings were 5 ratings, which was only on 1 resources.
  • 294 resources received 350 bookmarkings. 14% received more than one bookmark, average 1.19. Top amont of bookmarks were 5, which was only on 2 resources.
58.5% of annotations were on new resources, and 41.5% on old ones. They were distributed rather differently, the "old" resources received on the average more annotations than the new ones.
  • 38 Travel well resources received annotations 99. 63 of them received more than one annotation, average is 2.6 each. The top one received 12 annotations.
  • 97 previously annotated resources (this includes 32 resources that were discovered during this period and annotated later by other new users) received 209 annotations. Average is 2.15 annotations per resource.
6. Story of the Travel well list

Barely about 15% of the 88 resources on the list were re-discovered by the new users! Previously we saw that these resources received a good amount of "hits" and eyeballs, but not so many of them actually resulted in ratings, and when they did, they were not equally distributed among the resources (Table 4). Only 18 of the annotations took place on the TW-list, otherwise, an additional 20 resources from this list were annotated on the SRL and tagcloud. So the success-rate of these recommendations was less than 50%! Can barely call these recommendations. I will look later which ones were "thumbed up" and which ones downed. As with the previously bookmarked resources, ahem, maybe the taste differs between the two sets of users.

Table 4


The resources on the "Travel well" list received many more hits (average 7.12) than just "any previously annotated resource" (average: 0.68).

Sunday, January 04, 2009

New users on the portal and resource discovery

I looked at 18 new users on the portal, and studied resources that they bookmarked. I wondered how many of these resources had previous annotations by users? By annotations I mean that previous users had added ratings on them and Favourited these resources. If this is the case, it's clearly shown on the portal.

But are these annotations persuasive? Do they help users make their decision better or faster?


I had two sets of data:
  • last 3.5 months (Aug to Nov 17 2008)
  • Nov 18 to Dec 18. This are my 18 users who had bookmarked 114 resources.

Out of these results, it seems that 2/3 of the resources that these new users bookmarked had no previous annotations on them! I have to verify this finding, because currently I lack data from March to July to see what was bookmarked then.

Table 1


Anyhow, let's see what the current mini-study holds. Out of the third of resources that were discovered by this group, about 25% had previous annotations on them. They were mostly done by users before this group got initiated on the portal, however, some were also discovered thanks to the bookmarking by this group.

Only about 8% of resources were discovered through a special list called "Travel well" resources. These resources have been added there by "EUNRecommender" which currently is hand operated, but mainly based on picks by other users from at least two different countries. I find this figure rather surprising, as this "Travel well" list is the first thing that the user sees when they come to the portal.

Anyhow, I find it cool that 25% of bookmarks by this group were resources that had previous annotations. What we cannot say, though, is whether these users could have found these resources without these annotations displayed publicly on the search result list. However, I think that my measures like "pick-up rate" and "overlap" among Favourites will help me sort that out.

Here is a visualisation of this. The huge node is "sos-rec" which means that these resources were previously annotated (rate, bookmark). What is called "EUN Recommender" are resources from the "Travel well list". Other than that, the new users are the nodes which are connected by edges to resources that they have bookmarked.

Right from the bat, we can see that 5 users had taken their totally own trails and bookmarked resources that no one had bookmarked before - quite cool!

Additionally, there are few users on the lower right hand corner who are only connected to the whole graph through one resource (user: 192682) and (user: 217391).

Monday, December 22, 2008

Share early: Paper on Evidence of cross-boundary use and reuse of digital educational resources

I finally sent off my paper to a journal. Exiting. The first comment was to cut it shorter by about 2500 words, even before they started reviewing it. Outch, I think I managed to do it, I have a copy of it here:

Vuorikari, R., Koper, R. (submitted). Evidence of cross-boundary use and reuse of digital educational resources. pdf
ABSTRACT: In this study we conducted an investigation on the server-end log-files of teachers’ Collections of educational resources in a number of content platforms. Our goal was to find empirical evidence from the field that teachers use and reuse learning resources that are in a language other than their mother tongue and originate from different countries than they do. We call these cross-boundary learning resources. We compared the cross-boundary reuse of educational resources to the general reuse figure of 20%, and find that it was either equal to or less than the general reuse. We further studied the coverage, the overlap and the pick-up rate of these resources, and propose steps that could improve the probability of discovery, use and reuse of cross-boundary resources.

I actually have a new academic homepage too, check it out http://elgg.ou.nl/rvu

Friday, December 19, 2008

How different is user behaviour on a portal from the ones who log-in to ones how do not?

I've recently done quite a few studies on users of learning resources portals, I've looked for example how do they tag resources in a multilingual context or how much use and reuse is there across the borders. In all cases the studies have concentrated on the small amount of the (minority) users who actually log in and had created Collections of resources: in Calibrate that was about 30% and in LeMill about 10%.

Now in MELT we've revised the logging scheme to collect the click-stream from users who don't log-in. We also have Google analytics, but I don't have those at hand right now. I looked at the data from last 3 months, from Aug 18 to Dec 18, and then only from the last month (Table 1).

What do users do on the portal?

The most popular activity on the portal is search, 64.29% of all actions on the portal are different types of searches. They result in "playing" the resources in 18.31% of all actions on the portal. 13.09% of all actions are contributing actions on the portal, this means adding a tag, bookmarking or rating it. The figure of contributing actions is actually a bit distorted, we count each tag, rating and bookmarking there. As each bookmark has average of 4.3 tags attached to it, it brings up the figure. Actually, the number of actions that contribute to "acting with an individual resource" is around 4.3% of all actions (i.e. add rate and bookmark). Other includes activities like view evaluation, view other users who have bookmarked the resources, etc.

Table 1


The downside here is not having the stats from Google analytics, so I cannot exclude our internal usage, which I know has been quite a lot, since we've been testing the portal internally. So the figures might be somewhat distorted...


What about users who log-in and the ones who don't?

About a month ago I invited some 260 teachers on the portal, so I was intrigued to see what had happened. 2 weeks ago I checked that 11% of these teachers had started their own account. But, it seems like much more have come about and cruised around the portal.

Table 2 presents the data from the last 4.5 months (Aug-December) where I have divided it in two slots: first months include pilot teachers and lots of testing, in the table it's erroneously called "First 2 months". The second slot covers the time from Nov 18 to Dec 18 when we invited the new teachers (Nov 18/19 in 4 different patches of invites). It is called "the 3rd month" in the tables (again, my mistake). Moreover, the top half of the table has data regarding users who log-in and the bottom with users who did not log in.

I have mostly the same attributes for both, how did they search; advanced, browsing by category and by tag cloud and how many resources they clicked on (play). The table also contains the number of sessions and number of actions. A session is one consecutive event when the user does something, it's logged. If left idel, the user is logged off in some time. An action is anything, a search, a click on a resource, on a tag, etc. Additionally, we have the contribution by logged-in users, these are tags, bookmarks and ratings.

Table 2


As you can see, most of the sessions (above 86%, the second last row) in both slots take place when users are not logged in. Actually, the percentage of sessions stays pretty regular in both slots. Moreover, regarding the actions, we can see that during first months they mostly (70%) came from non-logged in users. However, when we invited the new teachers, we see 10% increase in actions by logged in users (from 30% to 40%). That's positive, as it shows that some of the invited teachers were motivated to contribute.

There is actually quite big differences in what do these two groups of users do when they are on the portal. Where logged-in users spend about 1/3 of their actions in searching, non logged-in users spent about 2/3 of their actions in searching. Chart 1 shows this clearly, however, I must say that most likely the disparity between the number of searches and plays by non-logged in users in the first months are due to our internal testing. If you compare that to non logged-in users in the 3rd month, you see that there is already less searches and more plays.

There has been a difference since the new comers (3rd month): within the logged in users, the number of searches executed has gone down (10%), whereas the number of plays has gone up (from 17% to 23%). Among non-logged in users there is the same 10% drop in searches, but plays have gone up by 10% (from 16% to 27%)! That shows that the new comers were interested in seeing what kind of resources were out there in the portal.

Chart 1 can maybe be used to illustrate

Chart 1


One difference can be observed in how differently these two groups seem to search: with logged-in users the advanced search seems to be the more popular way to search (more than 50% of searches are advanced), whereas with the users who are not logged-in browsing (both by category and tag cloud) is more popular. During first months 54% of searches were browsing, which went slightly up (to 56%) during the 3rd month. The tag cloud was the biggest winner in both groups (logged-in and not) at the cost of advanced search. I assume the difference is due to the fact that people who are not logged in are interested in seeing what is out there and browse around to discover learning material.

In any case, if we look at the figures of non logged-in users within the 3rd month, it's intriguing how equally the searches are distributed across these different ways of searching. We'll keep an eye on this in the future (e.g. when we know that most non-logged clicks come from us testing the portal).

Consumers and contributors

In Table 3, where I again have data for users logged-in and not, and by periods of first months and the 3rd month, we see that when users are logged in, they do things differently. First of all, the logged-in users spare much smaller percentage of their actions in searching (average 33% to 75%), however, bizarrely, they still seem to "play" about the same amount of resources (around 20%).

Table 3


Within the 3rd month we see the percentage of plays growing. We can assume that the logs from the first months period are most likely influenced due to our internal testing of the portal, which often times includes making searches. We see that the percentage of plays go up for the non logged-in users within the last month (from 16% to 27%), which, I assume shows a more normal user-behaviour than what could be observed before.

This still indicates that there is lots of inefficiency when non-logged in users search: on the average during the 3rd month, for those logged-in, one "play" was a result of 1.2 searches, whereas with those not logged-in, one "play" was a result of 2.6 searches - lot of time lost in searching. From Table 2 we can observe that there was more browsing (non logged-in users 1 month), I wonder if that was the reason? Have to keep on eye at that one!

Most interestingly, 40% of actions by logged in users contribute are the ones that contribute something to the portal, they rate, tag and bookmark. Folks who do not log-in are consumers: they only search, click and leave (- which is fine too).

So all in all, if we look at all the actions on the portal, the contributing actions by logged in users amount to about 17%. Too bad that this figure did not go up in the 3rd month like some others did. Anyhow, it seems to follow the power-law of distribution (20-80), where small amount of people contribute a lot so that other people can take advantage of this work, also know as participation inequality by J.Nilsen (2006).


J.Nilsen (2006) Participation inequality: Encouraging More Users to contribute

Learning resources landscape

Learning resources come in all colours and shapes, that is for sure. They also come from all kinds of different places; repositories, portals, the web.... For a recent presentation and paper, I created this diagram to better depict the learning resources landscape. As I later had to remove this part from the paper to save place, I post it here.


Teachers use a plethora of ways to discover educational content online. Harvey et al. (2006) report on search strategies of 4500 US faculty members where Google-like searches are by far the most prominent (81%), second most important being own personal Collections of resources and also “portals” that provide links to disciplinary topics (55%). In our user group comprised of 45 language and science teachers in K-12 education, such diversity of strategies was also discovered: one third use national and regional educational repositories as their primary source of educational content, 28% use search engines, 21% said they create their own content, 7% use content from schoolbook publishers and 12% reported all of the above (Vuorikari, 2008a).

These search strategies also give an indication of the different types of resources that teachers use. Figure 1 illustrates a number of different sources of content that teachers use. First of all, on the horizontal axis we distinguish between platforms that have institutional support and the ones that are rather teachers’ community driven sources. On the vertical axis we distinguish between teacher-generated content and “other sources”. The latter encompasses a large number of providers from educational portals and repositories, schoolbook publishers to educational and non-educational sites created by a number of private and public stakeholders. This “other sources” category is essentially as large as a teacher’s pedagogical imagination is in taking advantage of the resources on the Internet.

This diagram allows us to draw a landscape for educational resources. In the upper left corner of the diagram, there are examples of institutional Learning Object Repositories (LOR), such as the ones managed by Educational Authorities (e.g. Learning Resource Exchange for schools and members of EdReNe) and other repositories that make educational content available. On the lower left corner we place initiatives like MIT OCW which is an institutional repository that makes available teacher-generated content. The lower right corner represents teacher-generated content in a community-driven environment (e.g., LeMill), whereas the upper right hand corner represents content that is found on the Internet from various sources and saved in community-driven environments like delicious.com. None of these boundaries are fixed and there are many in-between-models (e.g., LOR with both user-generated content and institutional ones). Our data sets for this study, which are presented in Table 1, cover a wide area of Figure 1. For learning resources we use Wiley’s (2002) definition of learning object as “any digital resources that can be reused to support learning”, as they vary greatly in granularity and other qualities.

Our evidence finding focuses on teachers in K-12 education in a European multilingual context. In the Europe Union area, where 497 million people (Eurostats) live from diverse ethnic, cultural and linguistic backgrounds, multilinguality has an important role (Council of Europe, 2007). There are 23 EU official languages, 3 alphabets, and some 60 other languages are part of the EU heritage and spoken in specific regions or by specific groups (COM, 2008). Multilinguality can be defined as a situation where several languages are spoken within a certain geographical area, as well as the ability of a person to master multiple languages. 56% of EU citizens say that they are able to hold a conversation in one language apart from their mother tongue, and 28% in at least two languages. English remains the most widely spoken foreign language throughout Europe (38%), second and third place is French (14%) and German (14%), whereas 6% have foreign language expertise in Spanish and Russian respectively. Over two-third say that they language lessons at school was the way they have learned foreign languages (COM, 2006).

..................

Harley, D., Henke, J., Lawrence, S., Miller, I., Perciali, I., and Nasatir, D. (2006). Use and Users of Digital Resources: A Focus on Undergraduate Education in the Humanities and Social Sciences. Available from
http://cshe.berkeley.edu/research/digitalresourcestudy/report/digitalresourcestudy_final_report.pdf

Vuorikari, R. (2008a). A case study on teachers' use of social tagging tools to create collections of resources - and how to consolidate them. In Wild, F., Kalz, M., Palmer, M (Eds) Proceedings of the First International Workshop on Mashup Personal Learning Environments. Available from http://sunsite.informatik.rwth-aachen.de/Publications/CEUR-WS/Vol-388/vuorikari.pdf

Wiley, D. (2002). The Instructional Use of Learning Objects. Online at: http://reusability.org/read

COM(2006). Europeans and their languages. Special Eurobarometer, European Commission.

COM(2008). 566 final. Multilingualism: an asset for Europe and a shared commitment, European Commission.

Council of Europe (2007). Un cardre Européen commun de référence pour les langues : apprendre, enseigner, évaluer. Division des Politiques Linguistiques, Strasbourg: France.

Thursday, November 06, 2008

Mind those backups! - stolen laptops

Oh boy, my digital misery does not seem to be over yet! After having my home broken into and my laptop stolen, I was dead-happy that the evil-minded robber left my external, one terabite back-up hard-drive right where it was, about 50 cm away from from the laptop that s/he stole.

Now about 10 days later I'm typing away using my new MacBook Pro. I must say that I was pretty happy to have restored my "life" using Time Machine, only about a week's worth of back-ups was missing. It felt great to log-in to my own desktop, have my applications restored just like that, and just start using my laptop like nothing happened. I even pledged to always do my backups.

Then I started noticing little things. Ops, my address book is missing. My bookmarks and passwords are missing in Firefox. Then, I wanted to upload a file, and I realised that ALL MY FILES ARE MISSING! WTF?

Those files are, for sure, on the back-up hard-drive, I can access them there. But for some reason, when importing "my life" from Time machine, it omitted to import my files. Hey, big deal, at least the file structure is there..dah.

Now I'm trying to discover an easy way to do that. I am finding all kinds of not so nice things on Time machine, like this.

Ok now, time to roll up my sleeves and start digging out those files. So far this post looks promising.

As a lesson learned: mind your back-ups!

Wednesday, November 05, 2008

Power of pursuation/example/recommendation

We plan to invite about 130 teachers to the portal and I'd like to make a little experiment on this. The idea is to show two different examples of how to access and discover learning resources on the portal, and see whether that has an influence on
  • Uptake: users sign up
  • Retention: users come back
  • Different ways to discover resources (social cues vs. conventional search strategies)
  • Focus on the system (discovery e.g. clicking on resources vs. contributing, e.g. bookmark and tag, rate, etc)
The point would be to test the statement from the results reported in Harper et al (2007), where an email newsletter with manipulated social comparison made no difference to a member's interest in using the system, but it changed their focus within the system.
While subjects who received an email message with the comparison manipulation were no more likely to click on one of the links or log in to the system, they were more likely to rate movies.
There are differences, but in grosso modo the idea has similarities: In Harper et al (2007) the manipulated social information in the email concerned the subject him/herself (treatment group), whereas in my case the information would be about some other teachers that the subjects would be able to relate with (e.g. see favourites from a science or language teacher). The biggest difference would be that there is no comparison aspect of the subject's performance to the other users in the system, which was one of the central features of Harper et al study.

Study design

The randomly selected treatment group would receive an invitation with set goals of expectations on the use of the portal. Examples will be given on how to access and discover learning resources based on social navigation cues, show examples of how to browse other user's Favourites and how to access resources through a tag cloud.

The randomly selected control group will
receive an invitation with set goals of expectations on the use of the portal. Examples will be given on how to access and discover learning resources would receive an invitation where examples would be given on how to access and discover learning resources based on conventional free text search or browsing keywords
(to be reworked, just initial ideas based on tracking methods that I could use).
  • Immediate reaction: number of people who access the portal through the direct links on the invitation as opposed to the number of people who access the portal though the main page. the time these people spend on the portal on the first time and how they search, how many searches they execute and how many resources they click on
  • Uptake: is there difference between the groups on signing up on the portal?
  • Retention: on the longer run, say, within a month, do they still come back
  • Different ways to discover resources (social cues vs. conventional search strategies)
  • Focus on the system (discovery vs. contributing in terms of ratings, tagging, etc) : do people who see examples of social navigation use these methods more than the control group? are there any differences how many resources the subjects in both groups tag and rate?

Hypothesis to test
(to be reworked, just basic ideas)

hypotheses would be that subjects in the treatment group will discover more resources than the control due to social navigation cues made readily available to them. By discovering I mean that they click on these resources on the portal to view them. I also would hypothesise that the retention rate is better among the treatment group, as they get a direct access to selected resources whereas the control group has to look for the interesting resources and might get diverted there.

Relevant studies in this direction, to be completed

A study towards this direction was reported by Harper et al (2007). They study the effect of email newsletters that told the community members whether their contribution was above or below average. They report that a) previous studies has shown that information about social norms can affect contributions, e.g. people recycled more material when they were provided with information about how much other people had recycled (Schultz, 1999).


Social Comparisons to Motivate Contributions to an Online Community.
, Harper, F.; Li, X.; Chen, Y.; Konstan, J. , Persuasive Technology, 26/04/2007, Palo Alto, CA, (2007)

Using Social Psychology to Motivate Contributions to Online Communities, Ling, K.; Beenen, G.; Ludford, P.; Wang, X.; Chang, K.; Li, X.; Cosley, D.; Frankowski, D.; Terveen, L.; Rashid, A.M.; Resnick, P.; Kraut, R. , Journal of Computer-Mediated Communication, Volume 10, Issue 4, (2005)

Changing Behavior With Normative Feedback Interventions: A Field Experiment on Curbside Recycling (1999)
by P Schultz

Monday, November 03, 2008

Web 2.0 = Learning 2.0?

Last week I was part of an expert workshop on Learning 2.0. It was organised by the Institute for Prospective Technological Studies (IPTS), one of the European Commission's research institutes. They currently run a year-long study on the Impact of Web 2.0 Innovations on Education and Training in Europe. The objective is to assess the impact of Web 2.0 trends on the field of learning and education in Europe, and to propose avenues for further research and policy-making in Europe.

It was very cool to be part of this group, we were about 30 people with various backgrounds and our main job was to looked at the preliminary results of two studies. We first discussed the intermediate results of an exploratory study that seeks to identify and analyse the existing practices related to the Web 2.0 initiatives in the field of learning in Europe. For this reason, a Learning 2.0 database had been set-up where practitioners were able to report their cases. A presentation of this study is available.

The second part of the validation workshop focused on the cases studies: Case study on 'Good Practices for Learning 2.0: Innovation' and Case study on 'Good Practices for Learning 2.0: Inclusion'.

A lot of the workshop time was spent on brainstorming mode, which is something that I truly enjoyed. The point was to try to identify what would be the NEW in what was called Learning 2.0. That's pretty tough, as we hardly know what is the new thing in Learning 1.0! Here is one image of our brainstorming chart, thanks to Graham!


The most skepticism, if I could even call it that as many of us were very enthusiastic about the potential of Web 2.0 for education, was that how can Web 2.0 technologies and tool help the learning, or can they help it at all?

Lots of things could and have been listed by the proponents of Web 2.0, like personalisation, participation, collaboration, motivation, social skills, reflection and meta-cognition. Those, however, are not inherit to Web 2.0, but to any good learning!

So is there anything that makes learning with Web 2.0 so special? In contrary to encouraging reflective learning, Web 2.0 seem to promote sporadic grasshopper minds, like some current studies on multitasking suggest.

What the workshop could say, though, was that more well coordinated research on Learning 2.0 is needed to better understand its potential. One such study in this direction is the new Becta study, which is very impressive.

Some links to other literature that folks in the workshop pointed out: http://delicious.com/tag/iptsl20

Also, check out the literature reviews and other studies that have already come out of Learning 2.0 or are about to come out. There are interesting things going on!

From the Learning 2.0. site:

The rapid growth of social computing or web 2.0 applications and supporting technologies (E.g. blogs, podcasts, wikis, social networking sites, sharing of bookmarks, VoIP and P2P services), both in terms of number of users/subscribers and in terms of usage patterns leads to the fact that the phenomena are also increasingly being used in the educational field and for learning purposes. As it enables different types of learning and teaching settings (formal, non-formal and informal), it is an important driver of innovation in learning.

Description: The Learning 2.0 study will

1. Identify and analyse the existing practices and related success factors of major web 2.0 initiatives in the field of learning in Europe;
2. Look at the innovative dimension of using web 2.0 for learning;
3. Analyse the position of Europe vs. the rest of the world in terms of quantitative and qualitative use of innovative Learning 2.0 approaches;
4. Discuss the potential of social computing applications to (re)-connect groups at risk-of-exclusion;
5. Propose avenues for further research and policy-making.


Friday, September 19, 2008

Encourage lurking in conferences!

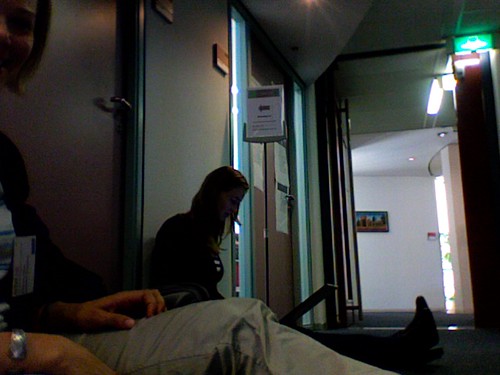
I'm always amazed how old-school these conferences are. I'm currently in Ec-Tel 08, sitting outside of the session room on the floor and listening the speech through the half-open door. I'm a lurker.
lurking in ectel08
I do not want to participate in the whole session, but I do want to lurk around because I'm half interested and there is one speaker that I want to see later. I just don't want to sit in the room and tap on my laptop.

It would be great to have a couch or a few seats outside of a session room with a screen, and hopefully also audio, to be able to properly lurk. We already know from online communities that it is totally OK to lurk, so why would we not make it also properly available in the conferences, too?

I've had really interesting conversations in these marginal places of conferences. Let's just make them happen more often! Let's provide places to officially lurk around.

Friday, September 12, 2008

Cross-boundary ranking of learning resources

Based on the idea of Interest Indicators, like social bookmarks and ratings, I've looked at the data so that we can make the cross-boundary resources better available on the MELT portal.
The aim is that we can, based on previous users' behaviour :

a) make separate "travel well" lists of resources that have a potential to cross-borders better,

b) use this information to rank resources better in the normal search result list,

c) allow users search for resources that have a good "travel well" value (e.g. give me resources in math that can cross-borders)

This is the data that I'm using (table below) and this is how I've defined cross-boundary (e.g. cross-country and language) learning resources before. Using that definition I have manually verified the number of cross-country resources. In the dataset, about 82% of resources were cross-country.


Now, we have a problem, though. On our MELT portal we do not have information about the country where the resource originates from. Dah!

This is a big blunder (in my opinion) in our Application Profile, we have not defined the country where the resource originates. We do define the provider, and the country information could be inferred from the provider, but it does not always work.

For example, one of our providers has frequently metadata about resources that do not originate from the same country!

I've experimented with the data using the information that we have on the portal, which is LOM about the resource including the language of the resource. As we also know the mother tongue of the registered users, this gives us a kick.

In the table below we can see the coverage of cross-boundary actions that we can get on resources without using any manual labour or verification of the country or language. As a base-line, with manual verification I found that 82% of the actions concerned cross-border rating or bookmarking of a resource.


The first row represents the cross-language resources (i.e. user's mother tongue is different from the resource language). Just using this information, we get about 65% of resources right, as opposed using manual checking (82%). I think it's pretty good, I'd settle for that! (although I have to look what kind of material was left out!)

The two other comparisons in the table are based only using information about users' previous behaviour. These would be:
  • rating > 2
  • bookmark
Only using information regarding bookmarked and rated resources results in a lousy coverage of around 20%. The problem is that 25% of resources bookmarked or rated are on more than one resource, the data still is very sparse.

Anyway, I want to use that information to "cross-boundary rank" the resources. As we do not know the country where the resource comes from, my work-around is based on countries where these users come from.

Here is a visualisation about resources that have been bookmarked or rated by users (see also ManyEyes link below). We can see the orange node in the middle, a learning resource called "Five Days in New York..". We see 3 edges leading out to Finland, Belgium and Hungary. This means at least one user from each of these countries has bookmarked the resource!

So, even if we do not know the origin of the resource, we know that it has users from 3 different countries. I can infer that it is a cross-boundary resource.

As most likely one of these 3 users come from the same country than the resource comes from, I will minus one country out of the total of countries: (number of countries -1)

My cross-boundary rank will be the following:
  • Count the number of ratings grater than 2 and/or bookmarks for a resource (actions). Give each action one point
  • Count the number of these users and give each user one point
  • Count the number of user countries of origin. Give each country one point and then minus 1
  • Compare the mother tongue of each of these users to the language of resource. If they differ, give one point/mismatch.
Then, count the following:
number of users + number of actions + number of cross-language x (number of countries -1)
Let's take the above resource "Five Days in New York.." as an example
  • Count the number of ratings grater than 2 (3) and/or bookmarks for a resource (5). Give each action one point. (8)
  • Count the number of these users and give each user one point (5)
  • Count the number of user countries of origin (Hungary, Finland, Belgium). Give each country one point and then minus 1 ( 3-1=2)
  • Count the number of user mother tongue (hu, nl, fi). Compare the mother tongue of each of these users to the language of resource (en). If they differ, give one point/mismatch (3).

  • number of users (5) + number of actions (8) + number of cross-language (3) x (number of countries -1) (2) = 32 Travel well value
This way you can count a value of "travel well" for each resource that users have previously interacted with on the portal. The value will always be an integer, which is important from the technical implementation point of view (in Lucine index it apparently needs to be an integer).

The down side is that we'll have a huge cold-start problem. As I said, our data is very sparse. To seed the system, I actually still manually check the new resources that users have interacted with and make a fake bookmark on them so that it looks like it has at least two users from 2 different countries. This way the resource gets a "travel well" value counted and appears on the "travel well" list and is better ranked, etc.

Of course, at the end I will evaluate how this treatment affects on users, do we, for example, see a big amount of bookmarks on these resources that I have been able to count a travel well value?

You can see a visualisation here. This is based on on user's country of origin.

Wednesday, September 03, 2008

Cross-boundary use of learning resources in LeMill

LeMill (http://lemill.net) is a web community for finding, authoring and sharing learning resources. It is divided to four sections: Content, Methods, Tools and Community. The main target audience is primary and secondary school teachers, but anyone can join. It is a wiki-like system where all the learning resources are published under open licence and can be edited by other members.

Registered users can publish learning content, and descriptions of educational methods and tools. Users can also create their own Collections of learning resources. About 10% of LeMill users have created collections (users total based on March 15 2008), this represents 188 users (data snapshot May 30 2008).

Collections are good for "Keeping found things found", the nice resources that you find in LeMill can be easily put in a collection. Another important thing is that Collections can be used to make content units or thematic lessons. Collections are actually folders that you give a name, you can make as many collections as you want.

For me the Collections tool is interesting. It's the whole thing about what content do users find interesting enough so that they want to keep it.

In Table 1 you can find the description of the data that I use for this study. I give quickly some descriptive statistics about it, and then drill into the Cross-Boundary use of learning resources. This this I mean that the user comes from a different country than the resource (cross-country) or the resource is in a different language than that of the user’s mother tongue (cross-language). If resource comes from a different country and is in a differnt language, then it's a cross-border resource. I'll give examples of this later to make it more clear.

What's in Collections?


Users had saved 1645 resources in 376 collections. There is 4.4 resources on the average in each collections. Some Collections are huge, the biggest has 82 resources in it, whereas the median is 2 resources.

When we look at how the users have used this feature, we find a wide variety of cases. Just by looking at numbers, the most active user had 94 resources in Collections, whereas the average is 8,75 resources. Median is 3, so as usual, we have a group of very active users (30% above average) and lots of not-so-active users of this functionality.

When we look at the resources in Collections, we find that there are 1387 different resources. 13% of the resources exist in more than one collection, but most of the resources (1205) are put to only one Collection. Not much of an overlap there, which is a bit surprising seen the fact that other users' Collections are public, so I can easily go and see the lessons created by others. There are nice pivotal navigational features that allow me to click on the other user's name and see their Collections. To my dismay, though, I noticed that it is not very easy to add resources from other users' Collection to mine, which might hinder the reuse a bit.

Who uses Collections?

The cool thing about LeMill is that their user-base is a total fruit bowl. There are users registered from all over, in this dataset we have 22 countries. The top number of Collections are Estonians, that's 45% of all resources in Collections. Others are Lithuania (14%), n/a (14%), Hungary (9%), and so on.

Where do resources come from in Collections?

It seems like most Estonians put resources made by another Estonian in their collections (48.5%). Then we have n/a "country" (13.2%), resources from Lithuania (11.4%), from Finland (7.5%), Hungary (6.6%), resources from Georgia (6.2%) and so on.

What about resources originating from different countries than the user? The case of crossing boundaries.

About 40% of Collection users are Cross-Boundary users (74). You can see this at the lower part of the 2nd Table above. I was able to calculate this by looking into the resources that they have put in their Collections. I found out that every fourth (419) resource in Collections crosses some boundaries, either language or country boundaries. Let's look at this in more details (Table here on the left).

1st Case are Cross-border resources: the resource comes from a different country than the user and is also in a different language than the mother tongue. 28% of the cases were like this.

Example
: a German resource from a German teacher that a Finnish teacher has put in his Collection.

2nd Case is about crossing language borders. Most cases (76%) represent resources that are in a different language than the mother tongue of the user is. Many of these resources are in English (63%) even if they are not created by an English native speaker.

Example
: Let's say an Estonian teacher has made a learning resource in English and put it in her own Collection.

3rd Case: Cross-country resource. These are resources that are in the user's mother tongue, but come from a different country. Much less of those, only less than 5%.

Example: A resource in English made by an American and put in a Collection by a Canadian. Or it could be a German resource added into a Collection by an Austrian teacher.


So are there any commonalities in this?


In LeMill, it looks like most cross-boundary actions (i.e. resources put in Collections) are within users' language skills (lower part of the Table on the left). You'd be surprised to learn the language skills these teachers have! Most of them have one additional language on top of their mother tongue, but many of them boast 3 or 4. This results that most of the 352/419 cross-boundary resources in collections are within Foreign language skills of these users. That's 84%.

Naturally, one is curious to know what those remaining 16% of resources are?
Actually, a bit disapointingly, there were little surprise (and very little of evidence on my last post on "Vygotsky's psychological tools". Many of these resources were in English, most likely the user had forgotten to mention that s/he masters this lingua franca. Remaining were either with no text or multimedia, some resources I was not able to locate in LeMill anymore. I put some of them in my Travel Well Collection.